如何扩展你的模型(7):Transformer 推理全知道
中英对照第 7 篇:推理引入了延迟这个新维度,也改变了显存版图——KV cache、batching、prefill/decode、Paged Attention、投机采样与 P/D 分离。左栏原文,右栏译文。
本篇属于系列 如何扩展你的模型(How To Scale Your Model) · 第 7 篇
原文:How To Scale Your Model(Google DeepMind,作者 Jacob Austin、Sholto Douglas、Roy Frostig、Anselm Levskaya、Charlie Chen、Sharad Vikram、Federico Lebron、Peter Choy、Vinay Ramasesh、Albert Webson、Reiner Pope)。
本站是中英对照排版:左栏是英文原文,右栏是对应的中文译文。不好直译的术语(roofline、strong scaling、ICI、MXU、KV cache、FSDP、TP 等)保留英文写法;原文配图全部保留。
本文是系列《如何扩展你的模型(How To Scale Your Model)》的第 7 篇,共 13 篇。系列目录。
原文以 MIT 许可证发布,版权归 Google LLC;本译文仅作学习交流之用,如有错漏以原文为准。
The Basics of Transformer Inference
Transformer 推理基础
So you’ve trained a Transformer, and you want to use it to generate some new sequences. At the end of the day, benchmark scores going up and loss curves going down are only proxies for whether something interesting is going to happen once the rubber hits the road! (Historically, you can do a surprising amount of research on Transformers without ever touching inference — scoring-based multiple choice benchmarks can be run efficiently without a proper KV cache or generation loop implementation. This meant, especially in research codebases, there’s often a lot of low hanging fruit in the inference codepath.)
假设你已经训练好了一个 Transformer,现在想用它生成一些新序列。说到底,benchmark 分数上涨、loss 曲线下降,都只是在代理「真正上路之后会不会有有趣的事情发生」而已!(从历史上看,你可以在完全不碰推理的情况下对 Transformer 做出惊人的研究成果——基于打分的多选题 benchmark 不需要真正实现 KV cache 或生成循环也能高效跑完。这也意味着,尤其是在研究代码库里,推理代码路径上常常有大量唾手可得的优化空间。)
Sampling is conceptually simple. We put a sequence in and our favorite Transformer will spit out $$\log p(\text{next token}_i \vert \text{previous tokens})$$, i.e. log-probabilities for all possible next tokens. We can sample from this distribution and obtain a new token. Append this token and repeat this process and we obtain a sequence of tokens which is a continuation of the prompt.
采样在概念上很简单。我们输入一段序列,我们心爱的 Transformer 会吐出 $$\log p(\text{next token}_i \vert \text{previous tokens})$$,也就是对所有可能的下一个 token 的对数概率。我们可以从这个分布里采样,得到一个新 token。把这个 token 追加到后面,重复这一过程,就得到一段作为 prompt 延续的 token 序列。
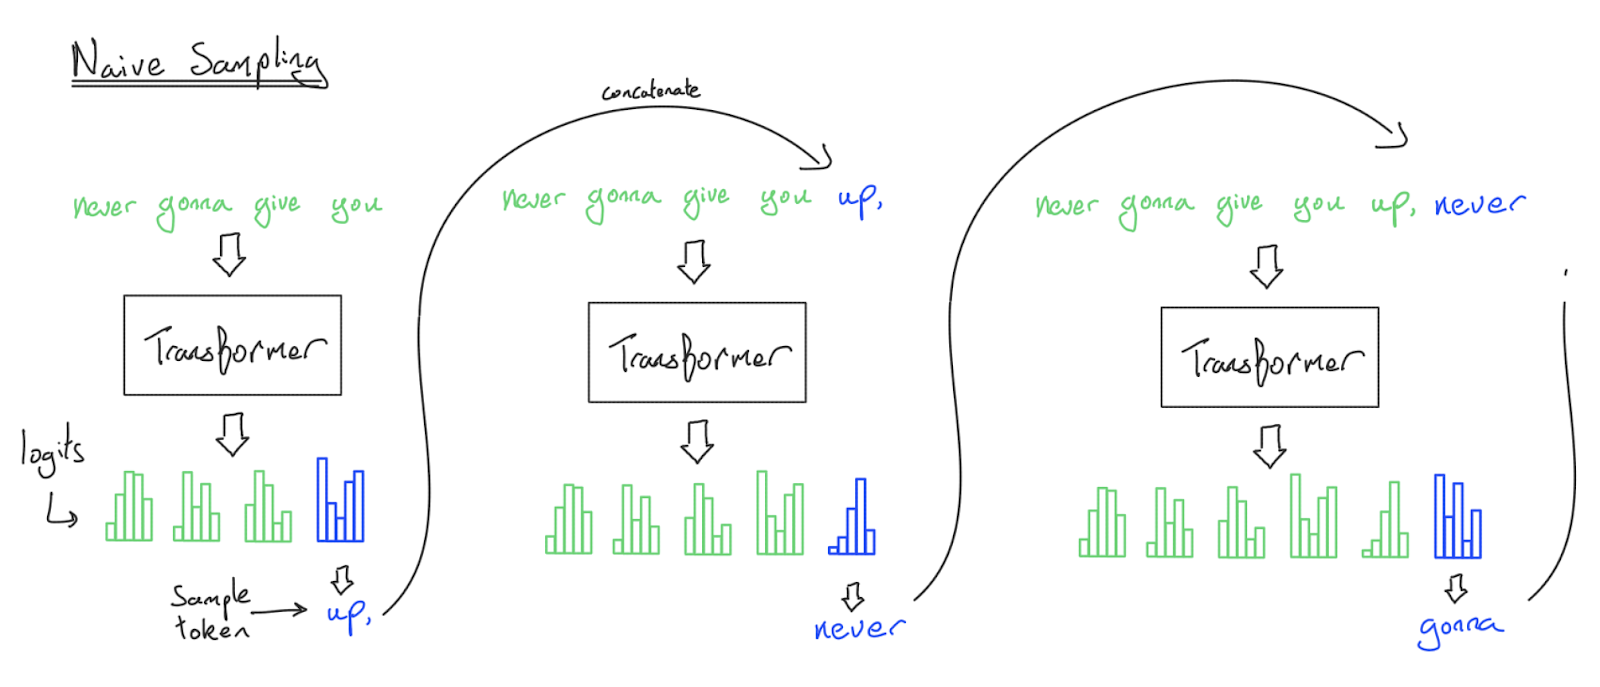
We have just described the naive implementation of Transformer sampling, and while it works, we never do it in practice because we are re-processing the entire sequence every time we generate a token. This algorithm is $$O(n^2)$$ on the FFW and $$O(n^3)$$ on the attention mechanism to generate $$n$$ tokens!
我们刚刚描述的是 Transformer 采样的朴素实现。虽然它能用,但实践中我们从不这么做,因为每生成一个 token 都要重新处理整段序列。要生成 $$n$$ 个 token,这个算法在 FFW 上是 $$O(n^2)$$、在注意力机制上是 $$O(n^3)$$!
How do we avoid this? Instead of doing the full forward pass every time, it turns out we can save some intermediate activations from each forward pass that let us avoid re-processing previous tokens. Specifically, since a given token only attends to previous tokens during dot-product attention, we can simply write each token’s key and value projections into a new data structure called a KV cache. Once we’ve saved these key/value projections for past tokens, future tokens can simply compute their $$q_i \cdot k_j$$ products without performing any new FLOPs on the earlier tokens. Amazing!
怎么避免这一点? 与其每次都做完整的前向传播,我们可以把每次前向传播中的一些中间激活保存下来,从而避免重新处理之前的 token。具体来说,由于在点积注意力中,每个 token 只关注它前面的 token,我们只需把每个 token 的 key 和 value 投影写进一个新的数据结构,称为 KV cache。一旦把过去 token 的 key/value 投影存下来,未来的 token 就可以直接计算它们的 $$q_i \cdot k_j$$ 乘积,而无需对更早的 token 再做任何新的 FLOPs。太妙了!
With this in mind, inference has two key parts:
有了这个认识,推理有两个关键部分:
- Prefill: Given a long prompt, we process all the tokens in the prompt at the same time and save the resulting activations (specifically, the key-value projections) in a “KV cache”. We also save the logits for the last token.
- Generation: Given a KV cache and the previous logits, we incrementally sample one token from the logits, feed that token back into the Transformer, and produce a new set of logits for the next step. We also append the KV activations for that new token to the KV cache. We repeat this until we hit a special
<EOS>token or reach some maximum length limit.
- Prefill(预填充):给定一段很长的 prompt,我们一次性处理 prompt 中的所有 token,并把产生的激活(具体来说是 key-value 投影)保存进一个 「KV cache」。我们还会保存最后一个 token 的 logits。
- Generation(生成):给定 KV cache 和上一步的 logits,我们从 logits 中增量地采样一个 token,把它喂回 Transformer,并为下一步产生一组新的 logits。我们还会把这个新 token 的 KV 激活追加到 KV cache。如此重复,直到遇到特殊的
<EOS>token 或达到某个最大长度限制。
Here’s a diagram of sampling with a KV cache:
下面是使用 KV cache 采样的示意图:
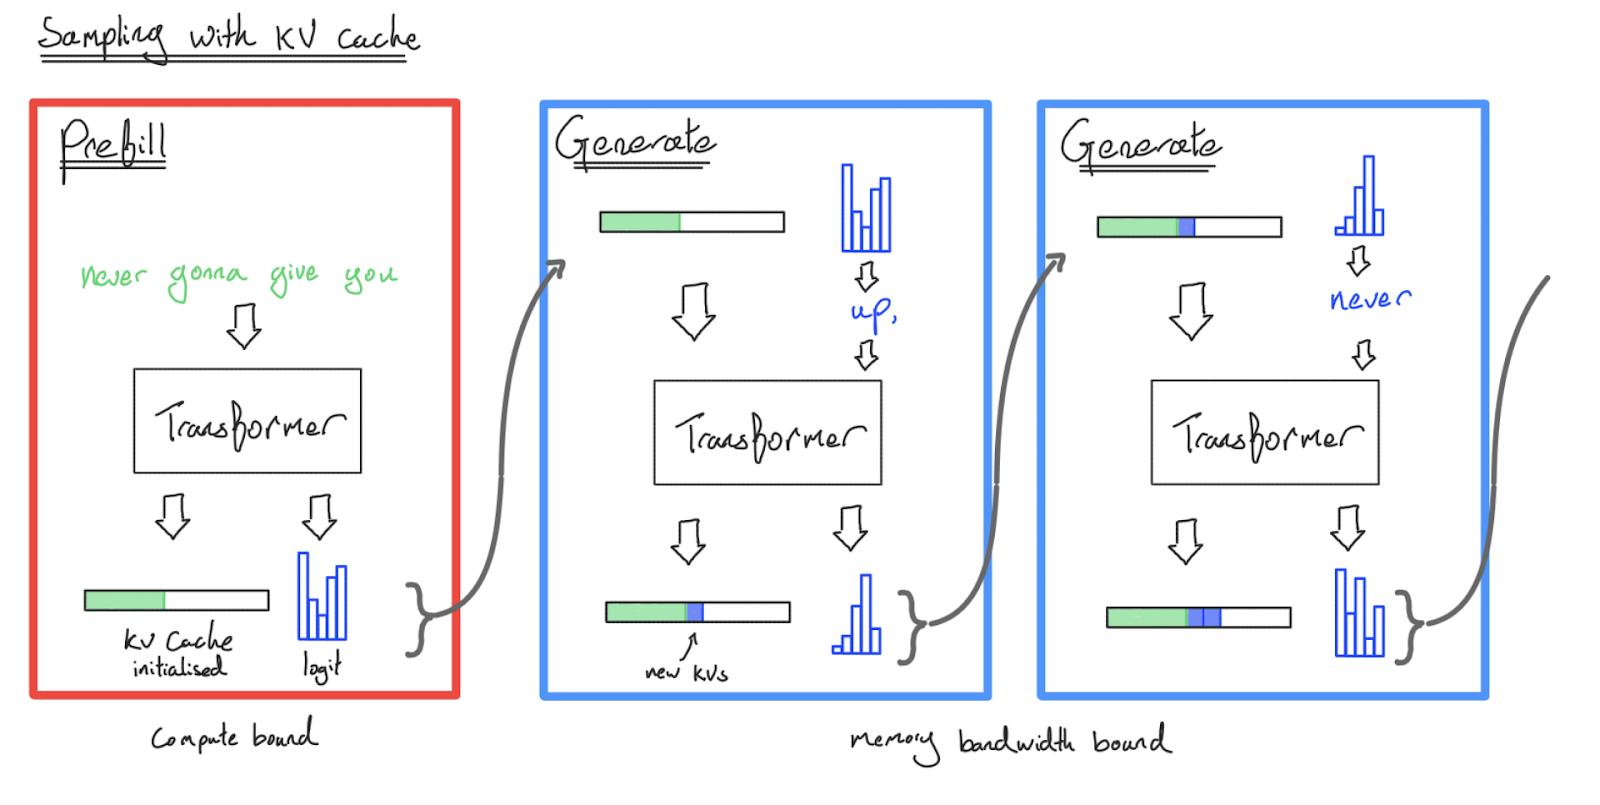
By sampling with a KV cache, we’ve reduced our time complexity to generate $n$ tokens to $$O(n)$$ on the FFW and $$O(n^2)$$ on the attention, since we never reprocess a previous token. However, many forward passes are still needed to generate a sequence — that’s what’s happening when you query Gemini or ChatGPT and the result streams back to you. Every token is (usually) a separate (but partially cached) Transformer call to a massive model.
借助 KV cache 采样,我们把生成 $n$ 个 token 的时间复杂度降到了 FFW 上的 $$O(n)$$ 和注意力上的 $$O(n^2)$$,因为我们从不重新处理之前的 token。不过,要生成一段序列仍然需要很多次前向传播——当你查询 Gemini 或 ChatGPT、结果以流式返回时,发生的正是这件事。每个 token 通常都是一次对巨型模型的独立(但部分命中缓存的)Transformer 调用。
We will soon see that prefill and generation are very different beasts — Transformer inference is two tasks in disguise! Compared to training, the KV cache is also a novel and significant source of complexity.
我们很快就会看到,prefill 和 generation 是完全不同的两种野兽——Transformer 推理其实是伪装成一件事的两个任务!与训练相比,KV cache 也是一个全新且重要的复杂度来源。
What do we actually want to optimize?
我们到底想优化什么?
Before we proceed further, it’s worth highlighting one aspect of inference that’s totally new: latency. While during training we only care about throughput (total tokens processed per second per chip), during inference we have to worry about how fast we’re producing tokens (both the Time To First Token (TTFT) and the per-token latency). For example:
在继续之前,值得强调推理中一个全新的方面:延迟。训练时我们只关心吞吐(每颗芯片每秒处理的 token 总数),而推理时我们必须关心产出 token 的速度(既包括 Time To First Token(TTFT,首 token 时间),也包括每 token 延迟)。例如:
- Offline batch inference for evals and data generation only cares about bulk cost of inference and is blind to the latency of individual samples.
- Chat interfaces/streaming tasks need to run cheaply at scale while having low TTFT and generating tokens fast enough to exceed human reading speed.
- Edge inference (e.g.
llama.cppon your laptop) only needs to service one user at a time at the lowest possible latency, potentially with heavy hardware constraints.
- 离线批量推理(用于评测和数据生成)只关心推理的批量成本,对单个样本的延迟不敏感。
- 聊天界面 / 流式任务需要在规模化下便宜运行,同时拥有低 TTFT,并且生成 token 的速度要超过人的阅读速度。
- 边缘推理(例如你笔记本上的
llama.cpp)只需一次服务一个用户,追求尽可能低的延迟,并且可能面临很重的硬件约束。
Maximizing hardware utilization is still critical and helps with cost and TTFT, but unlike training, it does not necessarily translate to better experience for individual users in all contexts. Many optimizations at the accelerator, systems and model architectural level make tradeoffs between latency, throughput, context length and even model quality.
最大化硬件利用率仍然至关重要,它有助于降低成本、改善 TTFT;但与训练不同,它并不必然在所有场景下都转化为单个用户更好的体验。加速器、系统和模型架构层面的许多优化,都要在延迟、吞吐、上下文长度乃至模型质量之间做取舍。
A more granular view of the Transformer
更细粒度地看 Transformer
So far we’ve mostly treated a Transformer as a stack of feedforward blocks. While this is often reasonable from a FLOPs and memory standpoint, it’s not sufficient to properly model inference. (One thing you’ll notice throughout this section is that inference is much less forgiving than training. We typically have far fewer FLOPs, less opportunity for batching, and a much greater sensitivity to latency. KV caches dramatically complicate inference as well.) As we saw in Part 4, the major components of a Transformer forward pass are:
到目前为止,我们大多把 Transformer 当作一摞前馈块。从 FLOPs 和显存的角度看这通常合理,但要正确建模推理就不够了。(本节里你会注意到一件事:推理比训练苛刻得多。我们通常只有少得多的 FLOPs、更少的 batching 机会,而且对延迟灵敏得多。KV cache 也让推理的复杂度大幅上升。)如第 4 部分所述,Transformer 前向传播的主要组成部分是:
- A bunch of linear operations, including the MLP ($W_{in}$, $W_{out}$) and the attention QKV projections and output projections ($W_Q$, $W_K$, $W_V$, and $W_O$). These all involve reading parameters and a batch of activations from HBM, doing some FLOPs, and writing the result back to HBM.
- Dot-product attention. We need to read a batch of key-value projections and a batch of query activations from HBM, do a few inner products and some softmax operations, and write the attention result back to HBM.
- Everything else, including applying layer norms, activation functions, token sampling, updating KV caches, and positional embeddings. These do take some FLOPs, but are dominated by, or fused into, the above.
- 一堆线性运算,包括 MLP($W_{in}$、$W_{out}$)以及注意力的 QKV 投影和输出投影($W_Q$、$W_K$、$W_V$ 和 $W_O$)。它们都涉及从 HBM 读取参数和一批激活、做若干 FLOPs、再把结果写回 HBM。
- 点积注意力。我们需要从 HBM 读取一批 key-value 投影和一批 query 激活,做若干内积和一些 softmax 运算,再把注意力结果写回 HBM。
- 其他一切,包括应用 layer norm、激活函数、token 采样、更新 KV cache 和位置编码。这些确实要花一些 FLOPs,但都被上面两项主导,或被融合进上面两项。
For the next couple of sections, we’re going to look at each of these in the context of prefill and generation and ask what is likely to bottleneck our performance. Within a single accelerator, are we compute-bound or memory-bound? We want to emphasize how different the answers will be for prefill versus generation.
接下来几节,我们会在 prefill 和 generation 的语境下逐一考察这些部分,并问:什么最可能成为性能瓶颈?在单颗加速器内部,我们是计算受限还是显存受限?我们想强调的是,prefill 和 generation 的答案会有多么不同。
Linear operations: what bottlenecks us?
线性运算:瓶颈在哪里?
All our linear operations are conceptually the same, whether they live in the MLP block or attention. Their arithmetic intensity depends on the batch size. We did this math in Section 1 but it’s worth repeating. Let’s look at a single matrix multiply of a $\text{bf16[B, D]}$ batch by a $\text{bf16[D, F]}$ matrix. This could be the big MLP block ($W_\text{in}$ or $W_\text{out}$) or one of the smaller attention projections ($W_Q$, $W_K$, $W_V$, $W_O$). To do this matmul, we need to load both of these arrays from HBM into the MXU, do the multiplication, then write the result back to HBM. As before, we have:
我们所有的线性运算在概念上都一样,无论它们位于 MLP 块还是注意力里。它们的算术强度取决于 batch size。这个数学我们在第 1 节做过,但值得再重复一遍。来看一次 $\text{bf16[B, D]}$ 的 batch 乘以一个 $\text{bf16[D, F]}$ 矩阵的矩阵乘法。它可能是大 MLP 块($W_\text{in}$ 或 $W_\text{out}$),也可能是较小的注意力投影之一($W_Q$、$W_K$、$W_V$、$W_O$)。要做这次矩阵乘法,我们需要把这两个数组都从 HBM 加载到 MXU,做乘法,再把结果写回 HBM。和之前一样,我们有:
$$T_\text{math} = \frac{\text{Computation FLOPs}}{\text{Accelerator FLOPs/s}} = \frac{2BDF}{\text{Accelerator FLOPs/s}}$$
$$T_\text{comms} = \frac{\text{Communication Bytes}}{\text{Bandwidth Bytes/s}} = \frac{2BD + 2FD + 2BF}{\text{Bandwidth Bytes/s}}$$
A TPU or GPU can overlap these by loading as it does the compute, so to be compute-bound, we need $$T_\text{math} \geq T_\text{comms}$$, or:
TPU 或 GPU 可以在计算的同时加载,从而让二者重叠,所以要计算受限,我们需要 $$T_\text{math} \geq T_\text{comms}$$,即:
$$\frac{2BDF}{2BD + 2DF + 2BF} \geq \frac{\text{Accelerator FLOPs/s}}{\text{Bandwidth Bytes/s}} \underset{\text{TPU v5e}}{=} \frac{1.97E+14}{8.20E+11} = 240$$
where the RHS is the arithmetic intensity of our hardware. Now let’s assume $D$ and $F$ are very large compared to $B$ (usually our batches are at most 500 and $D$ and $F > 10k$), we can simplify the denominator by using the fact that $\small{2BD + 2DF + 2BF \approx 2DF}$ which gives us
其中右边是我们硬件的算术强度。现在假设 $D$ 和 $F$ 相比 $B$ 非常大(通常我们的 batch 最多 500,而 $D$、$F$ > 10k),我们可以利用 $\small{2BD + 2DF + 2BF \approx 2DF}$ 来化简分母,得到
$$\begin{align*} \frac{2BDF}{2BD + 2DF + 2BF} \approx \frac{2BDF}{2DF} \geq \frac{\text{Accelerator FLOPs/s}}{\text{Bandwidth Bytes/s}} \\ \underset{\text{TPU v5e}}{=} \frac{1.97E+14}{8.20E+11} \implies B \geq 240 = B_{\text{crit}} \end{align*}$$
If we quantize our weights or use lower precision FLOPs for the matrix multiplication, this critical batch size can change. For instance, if we quantize our weights to int8 or fp8, $B_\text{crit}$ decreases by 2x. If we do our FLOPs in int8 or fp8, $B_\text{crit}$ increases by 2x. Thus if we let $\beta = \text{bits per param} / \text{bits per activation}$ and $\alpha_\text{hbm} = C / W_\text{hbm}$, our critical batch size is actually $B_\text{crit} = \beta \alpha_\text{hbm}$.
如果我们把权重做量化,或者用更低精度做矩阵乘法的 FLOPs,这个临界 batch size 会变化。例如,把权重量化到 int8 或 fp8,$B_\text{crit}$ 会减半;而如果 FLOPs 用 int8 或 fp8 做,$B_\text{crit}$ 会翻倍。因此,若令 $\beta = \text{每个参数的 bit 数} / \text{每个激活的 bit 数}$、$\alpha_\text{hbm} = C / W_\text{hbm}$,我们的临界 batch size 实际是 $B_\text{crit} = \beta \alpha_\text{hbm}$。
Takeaway: Transformer matmuls are compute-bound iff the per-replica token batch size is greater than $B_\text{crit} = C / W_\text{hbm} \cdot (\text{bits per param} / \text{bits per activation}) = \beta \cdot \alpha_\text{hbm}$. For bf16 activations on TPU v5e, this is 240 tokens. For an H100, it is about 280 tokens.
结论: Transformer 的矩阵乘法计算受限,当且仅当每副本的 token batch size 大于 $B_\text{crit} = C / W_\text{hbm} \cdot (\text{每个参数的 bit 数} / \text{每个激活的 bit 数}) = \beta \cdot \alpha_\text{hbm}$。对 TPU v5e 上的 bf16 激活,这个值是 240 个 token;对 H100,大约是 280 个 token。
During training, we’ll have a high intensity during all our matrix multiplications because we reuse the same weights over a very large batch. That high arithmetic intensity carries over to prefill, since user prompts are typically hundreds if not thousands of tokens long. As we saw before, the hardware arithmetic intensity of a TPUv5e is 240, so if a sequence longer than 240 tokens is fed into a dense model running on this hardware at bf16, we would expect to be compute-bound and all is well. Prompts shorter than this can technically be batched together to achieve higher utilization, but this is typically not necessary.
训练时,我们所有矩阵乘法的算术强度都很高,因为同一份权重会在非常大的 batch 上复用了很多次。这种高算术强度会延续到 prefill,因为用户的 prompt 通常有几百甚至几千个 token。 如前所述,TPUv5e 的硬件算术强度是 240,所以只要喂给这个硬件上 bf16 稠密模型的序列长于 240 个 token,我们就能保持计算受限,一切顺利。比这更短的 prompt 技术上可以拼批来获得更高利用率,但通常没必要。
Takeaway: During prefill, all matrix multiplications are basically always compute-bound. Therefore, simply maximizing hardware utilization or MFU (Model FLOPs Utilization) is enough to maximize throughput-per-chip (cost) and latency (in the form of TTFT). Unless prompts are extremely short, batching at a per-prompt level only adds latency for small improvements in prefill throughput.
结论: 在 prefill 阶段,所有矩阵乘法基本上总是计算受限。因此,只要把硬件利用率或 MFU(Model FLOPs Utilization)最大化,就足以同时最大化每芯片吞吐(成本)和延迟(以 TTFT 的形式)。除非 prompt 极短,否则在单个 prompt 级别上拼批只会增加延迟,换来的 prefill 吞吐提升却很有限。
However, during generation, for each request, we can only do our forward passes one token at a time since there’s a sequential dependency between steps! Thus we can only (easily) achieve good utilization by batching multiple requests together, parallelizing over the batch dimension. We’ll talk about this more later, but actually batching many concurrent requests together without affecting latency is hard. For that reason, it is much harder to saturate the hardware FLOPs with generation.
然而在 generation 阶段,由于每一步之间存在顺序依赖,对每个请求我们只能一次一个 token 地做前向传播!因此我们只能(轻松地)通过把多个请求拼批、沿 batch 维度并行来获得好的利用率。后面我们会更详细地讨论这一点,但实际上,把许多并发请求拼批而不影响延迟是很难的。正因如此,用 generation 把硬件 FLOPs 吃满要难得多。
Takeaway: During generation, the total token batch size must be greater than $B_{\text{crit}}$ to be compute-bound on the linear/feed-forward operations (240 for bf16 params on TPU v5e). Because generation happens serially, token-by-token, this requires us to batch multiple requests together, which is hard!
结论: 在 generation 阶段,为了让线性 / 前馈运算计算受限,总的 token batch size 必须大于 $B_{\text{crit}}$(对 TPU v5e 上的 bf16 参数是 240)。由于 generation 是逐 token 串行发生的,这就要求我们把多个请求拼批,而这很难!
It’s worth noting just how large this is! Generate batch size of 240 means 240 concurrent requests generating at once, and 240 separate KV caches for dense models. That means this is difficult to achieve in practice, except in some bulk inference settings. In contrast, pushing more than 240 tokens through during a prefill is pretty routine, though some care is necessary as sparsity increases.
值得注意的是这个数字有多大! generate 的 batch size 为 240 意味着同时有 240 个并发请求在生成,对稠密模型来说就是 240 份独立的 KV cache。这意味着实践中很难做到,除非在某些批量推理场景下。相比之下,在 prefill 时推送超过 240 个 token 是家常便饭,尽管随着稀疏度上升需要多加小心。
Note that this exact number will differ on the kind of quantization and hardware. Accelerators often can supply more arithmetic in lower precision. For example, if we have int8 parameters but do our computation in bf16, the critical batch size drops to 120. With int8 activations and int8 params, it jumps back up to 240 since the TPUv5e can supply 400 TOPs/s of int8 x int8.
注意,具体数值会随量化和硬件而变。 加速器往往能在更低精度下提供更多算力。例如,如果参数是 int8 但计算用 bf16,临界 batch size 会降到 120;用 int8 激活和 int8 参数时,它又跳回 240,因为 TPUv5e 的 int8 x int8 能提供 400 TOPs/s。
What about attention?
那注意力呢?
Things get more complicated when we look at the dot-product attention operation, especially since we have to account for KV caches. Let’s look at just one attention head with pure multi-headed attention. In a single Flash Attention fusion, we (We’re simplifying a fair bit here by ignoring the non-matmul FLOPs in applying the softmax, masks etc. They should be overlapped with computation or HBM reads, but this can be non-trivial to do on certain TPU generations. While these details don’t change the main message, which is that KV caches are usually memory bound, they are worth paying attention to.):
看两个点积注意力运算时,事情会变复杂,尤其是我们还要考虑 KV cache。我们只看纯多头注意力中的一个注意力头。在一次 Flash Attention 融合中,我们(这里做了不少简化,忽略了应用 softmax、mask 等非矩阵乘法 FLOPs。它们本应与计算或 HBM 读取重叠,但在某些代 TPU 上这可能并不容易。虽然这些细节不改变主要结论——KV cache 通常是显存受限的——但值得注意。):
- Read the $Q$ activations of shape $\text{bf16[B, T, D]}$ from HBM.
- Read the $KV$ cache, which is a pair of $\text{bf16[B, S, D]}$ tensors from HBM.
- Perform $2BSTD$ FLOPs in the $$QK$$ matmul. With Flash Attention, we don’t need to write the $\text{bf16[B, S, T]}$ attention matrix back into HBM.
- Perform $2BSTD$ in the attention $$AV$$ matmul.
- Write the resulting $\text{bf16[B, T, D]}$ tensor back into HBM.
- 从 HBM 读取形状为 $\text{bf16[B, T, D]}$ 的 $Q$ 激活。
- 从 HBM 读取 $KV$ cache,即一对 $\text{bf16[B, S, D]}$ 张量。
- 在 $$QK$$ 矩阵乘法中执行 $2BSTD$ 次 FLOPs。用 Flash Attention 时,我们不需要把 $\text{bf16[B, S, T]}$ 的注意力矩阵写回 HBM。
- 在注意力的 $$AV$$ 矩阵乘法中执行 $2BSTD$ 次 FLOPs。
- 把结果张量 $\text{bf16[B, T, D]}$ 写回 HBM。
Putting it all together, we get:
把它们合起来,我们得到:
$$\text{Multiheaded Attention Arithmetic Intensity} = \frac{4BSTD}{4BSD + 4BTD} = \frac{ST}{S+T}$$
For prefill, $S=T$ since we’re doing self-attention, so this simplifies to $T^2 / 2T = T / 2$. This is great because it means the arithmetic intensity of attention during prefill is $\Theta(T)$. That means it’s quite easy to be compute-bound for attention. As long as our sequence length is fairly large, we’ll be fine!
对 prefill 而言,因为做的是自注意力,$S=T$,于是式子化简为 $T^2 / 2T = T / 2$。这很好,因为它意味着 prefill 阶段注意力的算术强度是 $\Theta(T)$。也就是说,注意力很容易做到计算受限。只要序列长度足够大,就没问题!
But since generation has a trivial sequence dim, and the $B$ and $D$ dims cancel, we can make the approximation:
但 generation 的序列维度是平凡的(只有 1),而 $B$ 和 $D$ 维度会约掉,于是我们可以做如下近似:
$$S \gg T = 1 \implies \frac{ST}{S+T} \approx 1$$
This is bad, since it means we cannot do anything to improve the arithmetic intensity of attention during generation. We’re doing a tiny amount of FLOPs while loading a massive KV cache. So we’re basically always memory bandwidth-bound during attention!
这很糟糕,因为它意味着我们无法在 generation 阶段改善注意力的算术强度。我们只做了极少量的 FLOPs,却要加载巨大的 KV cache。所以注意力阶段我们基本上总是显存带宽受限!
Takeaway: during prefill, attention is usually compute bound for any reasonable sequence length (roughly $\gt 480$ tokens) while during generation our arithmetic intensity is low and constant, so we are always memory bandwidth-bound.
结论: 在 prefill 阶段,只要序列长度合理(大约 $\gt 480$ 个 token),注意力通常是计算受限的;而在 generation 阶段,我们的算术强度低且恒定,所以总是显存带宽受限。
Why is this, conceptually? Mainly, we’re compute-bound in linear portions of the model because the parameters (the memory bandwidth-heavy components) are reused for many batch items. However, every batch item has its own KV cache, so a bigger batch size means more KV caches. We will almost always be memory bound here unless the architecture is adjusted aggressively.
从概念上讲,为什么会这样? 主要是因为模型中的线性部分之所以计算受限,是因为参数(显存带宽开销的大头)会在许多 batch item 之间复用。然而每个 batch item 都有自己的 KV cache,所以 batch size 越大,KV cache 越多。除非激进地调整架构,否则这里几乎总是显存受限。
This also means you will get diminishing returns on throughput from increasing batch size once params memory becomes comparable to KV cache memory. The degree to which the diminishing returns hurt you depends on the ratio of parameter to KV cache bytes for a single sequence, i.e. roughly the ratio $2DF / SHK$. Since $HK\approx D$, this roughly depends on the ratio of $F$ to $S$, the sequence length. This also depends on architectural modifications that make the KV cache smaller (we’ll say more in a moment).
这也意味着,一旦参数显存与 KV cache 显存相当,增大 batch size 带来的吞吐收益就会递减。递减对你的伤害有多大,取决于单条序列中参数字节与 KV cache 字节之比,即大致是 $2DF / SHK$。由于 $HK\approx D$,这大致取决于 $F$ 与序列长度 $S$ 之比。这也取决于那些让 KV cache 变小的架构改动(稍后我们会多谈一些)。
Theoretical estimates for LLM latency and throughput
LLM 延迟与吞吐的理论估计
From this math, we can get pretty good bounds on the step time we should aim for when optimizing. (Note: if there is one thing we want the reader to take away from this entire chapter, it’s the following). For small batch sizes during generation (which is common), we can lower-bound our per-step latency by assuming we’re memory bandwidth bound in both the attention and MLP blocks:
从这些数学出发,我们可以对优化时应瞄准的步时给出相当好的界。(注:如果整章只能让读者记住一件事,那就是下面这个。) 在 generation 阶段 batch size 较小(这很常见)时,我们可以通过假设注意力和 MLP 块都显存带宽受限,来给出每步延迟的下界:
$$\begin{equation*} \text{Theoretical Min Step Time} = \frac{\text{Batch Size} \times \text{KV Cache Size} + \text{Parameter Size}}{\text{Total Memory Bandwidth}} \end{equation*}$$
Similarly, for throughput:
同样地,对吞吐有:
$$\begin{equation*} \text{Theoretical Max Tokens/s} = \frac{\text{Batch Size} \times \text{Total Memory Bandwidth}}{\text{Batch Size} \times \text{KV Cache Size} + \text{Parameter Size}} \end{equation*}$$
Eventually, as our batch size grows, FLOPs begin to dominate parameter loading, so in practice we have the more general equation:
最终,随着 batch size 增长,FLOPs 开始主导参数加载,所以实践中我们有更一般的等式:
$$\begin{align} \tiny \text{Theoretical Step Time (General)} = \underbrace{\frac{\text{Batch Size} \times \text{KV Cache Size}}{\tiny \text{Total Memory Bandwidth}}}_{\text{Attention (always bandwidth-bound)}} + \underbrace{\max\left(\frac{2 \times \text{Batch Size} \times \text{Parameter Count}}{\text{Total FLOPs/s}}, \frac{\text{Parameter Size}}{\text{Total Memory Bandwidth}}\right)}_{\tiny \text{MLP (can be compute-bound)}} \end{align}$$
where the attention component (left) is never compute-bound, and thus doesn’t need a FLOPs roofline. These are fairly useful for back-of-the-envelope calculations, e.g.
其中注意力部分(左边)从不会计算受限,因此不需要 FLOPs roofline。这些式子对信封背面的估算相当有用,例如
Pop Quiz: Assume we want to take a generate step with a batch size of 4 tokens from a 30B parameter dense model on TPU v5e 4x4 slice in int8 with bf16 FLOPs, 8192 context and 100 kB / token KV caches. What is a reasonable lower bound on the latency of this operation? What if we wanted to sample a batch of 256 tokens?
小测验: 假设我们要在 TPU v5e 4x4 slice 上,从一个 30B 参数的稠密模型以 batch size 4 个 token 做一次 generate 步,参数用 int8、FLOPs 用 bf16,上下文 8192、每 token 的 KV cache 为 100 kB。这次操作的延迟的合理下界是多少?如果我们想采样一个 256 token 的 batch 呢?
Click here for the answer.
点击查看答案。
Answer: in int8, our parameters will use 30e9 bytes and with the given specs our KV caches will use 100e3 * 8192 = 819MB each. We have 16 chips, each with 8.2e11 bytes/s of bandwidth and 1.97e14 bf16 FLOPs/s. From the above equations, since we have a small batch size, we expect our step time to be at least (4 * 819e6 + 30e9) / (16 * 8.2e11) = 2.5 ms. At 256 tokens, we’ll be well into the compute-bound regime for our MLP blocks, so we have a step time of roughly (256 * 819e6) / (16 * 8.2e11) + (2 * 256 * 30e9) / (16 * 1.97e14) = 21ms.
答案: 在 int8 下,我们的参数会占用 30e9 字节,按给定规格我们的每份 KV cache 会占用 100e3 * 8192 = 819MB。我们有 16 颗芯片,每颗带宽 8.2e11 字节/秒、bf16 算力 1.97e14 FLOPs/s。由上面的公式,由于 batch size 很小,我们预期步时至少是 (4 * 819e6 + 30e9) / (16 * 8.2e11) = 2.5 ms。在 256 个 token 时,我们的 MLP 块已经稳稳进入计算受限区间,于是步时大约是 (256 * 819e6) / (16 * 8.2e11) + (2 * 256 * 30e9) / (16 * 1.97e14) = 21ms。
As you can see, there’s a clear tradeoff between throughput and latency here. Small batches are fast but don’t utilize the hardware well. Big batches are slow but efficient. Here’s the latency-throughput Pareto frontier calculated for some older PaLM models (from the ESTI paper[esti]):
如你所见,这里在吞吐和延迟之间存在明显的取舍。小 batch 快,但硬件利用率差;大 batch 慢,但高效。下面是针对一些较老的 PaLM 模型计算出的延迟-吞吐 Pareto 前沿(来自 ESTI 论文[esti]):
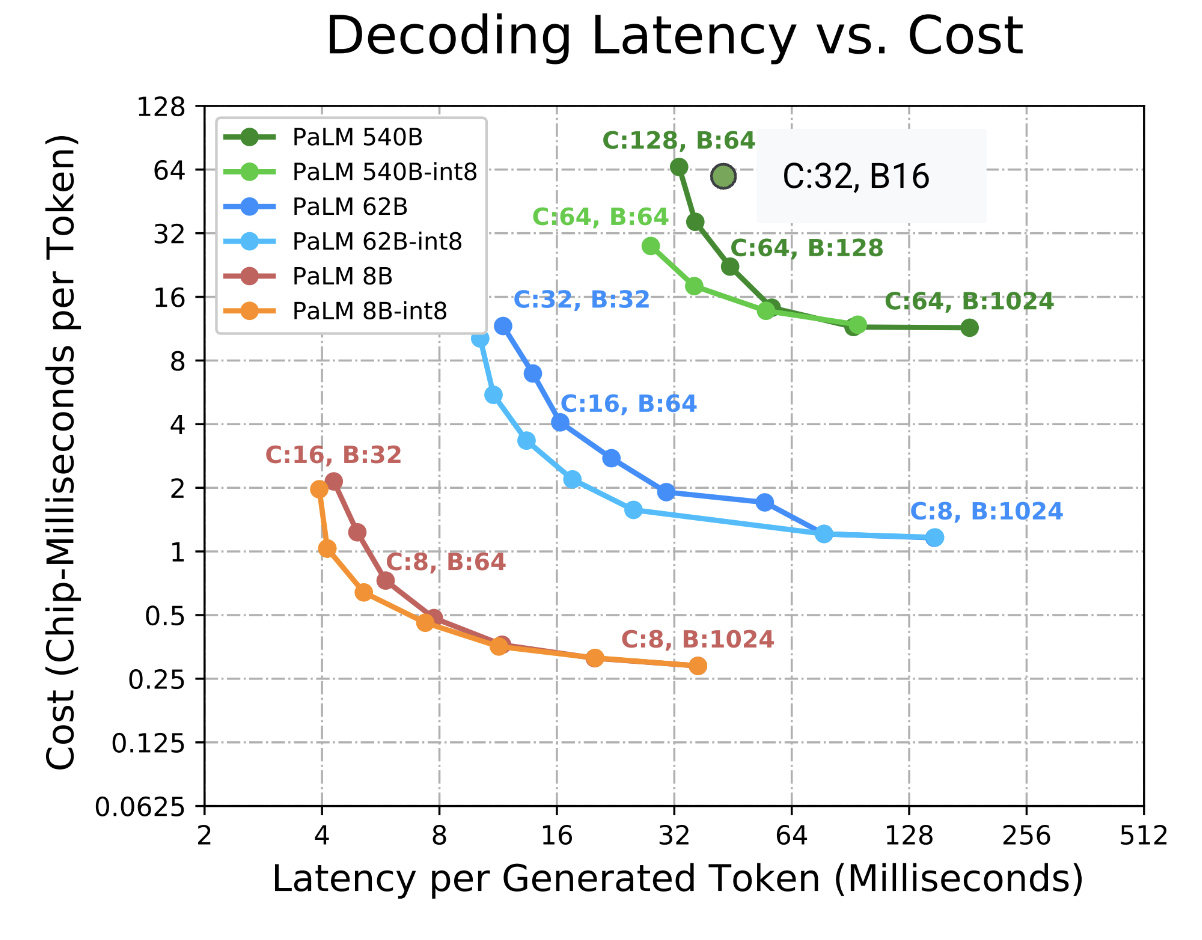
Not only do we trade off latency and throughput with batch size as knob, we may also prefer a larger topology to a smaller one so we can fit larger batches if we find ourselves limited by HBM. The next section explores this in more detail.
我们不仅可以用 batch size 作为旋钮来权衡延迟与吞吐;如果我们发现自己被 HBM 限制住,也可能更倾向于用更大的拓扑而不是更小的,以便装下更大的 batch。下一节会更详细地探讨这一点。
Takeaway: if you care about generation throughput, use the largest per-chip batch size possible. Any per-chip batch size above the TPU arithmetic intensity ($B_\text{crit}$, usually 120 or 240) will maximize throughput. You may need to increase your topology to achieve this. Smaller batch sizes will allow you to improve latency at the cost of throughput.
结论: 如果你关心 generation 吞吐,就用尽可能大的每芯片 batch size。任何高于 TPU 算术强度($B_\text{crit}$,通常为 120 或 240)的每芯片 batch size 都能最大化吞吐。为此你可能需要扩大拓扑。更小的 batch size 可以让你以牺牲吞吐为代价改善延迟。
There are some caveats to this from a hardware standpoint. Click here for some nits.
从硬件角度看,这里有一些注意事项。点击查看一些细节。
This is all quite theoretical. In practice we often don’t quite see a sharp roofline for a few reasons:
这些都非常理论化。实践中我们往往看不到那么锐利的 roofline,原因有几个:
- Our assumption that HBM reads will be perfectly overlapped with FLOPs is not realistic, since our compiler (XLA) is fallible.
- For sharded models, XLA also often fails to efficiently overlap the ICI communication of our model-sharded matrix multiples with the FLOPs themselves, so we often start taking a latency hit on linears over $$\text{BS}=32$$.
- Batch sizes larger than the theoretical roofline will still see some improvement in throughput because of imperfect overlapping, but this is a good heuristic.
- 我们假设 HBM 读取会与 FLOPs 完美重叠,这并不现实,因为我们的编译器(XLA)是会犯错的。
- 对分片模型来说,XLA 也常常无法高效地把模型分片矩阵乘法中的 ICI 通信与 FLOPs 本身重叠起来,所以当 $$\text{BS}=32$$ 以上时,我们往往开始在线性层上吃到延迟损失。
- 比理论 roofline 更大的 batch size 仍然会因重叠不完美而带来一些吞吐提升,但这是个很好的启发式。
What about memory?
那显存呢?
We’ve spent some time looking at bandwidth and FLOPs, but not at memory. The memory picture looks a lot different at inference time, thanks to our new data structure, the KV cache. For this section, let’s pick a real model (LLaMA 2-13B) to demonstrate how different things look:
我们已经花了一些时间看带宽和 FLOPs,但还没看显存。得益于新的数据结构 KV cache,推理时的显存图景大不相同。本节我们选一个真实模型(LLaMA 2-13B)来展示差异有多大:
| hyperparam | value |
|---|---|
| L (num_layers) | 40 |
| D (d_model) | 5,120 |
| F (ffw_dimension) | 13,824 |
| N (num_heads) | 40 |
| K (num_kv_heads) | 40 |
| H (qkv_dim) | 128 |
| V (num_embeddings) | 32,000 |
| 超参数 | 取值 |
|---|---|
| L (num_layers) | 40 |
| D (d_model) | 5,120 |
| F (ffw_dimension) | 13,824 |
| N (num_heads) | 40 |
| K (num_kv_heads) | 40 |
| H (qkv_dim) | 128 |
| V (num_embeddings) | 32,000 |
What’s using memory during inference? Well, obviously, our parameters. Counting those, we have:
推理时什么在占用显存?显然,是我们的参数。把它们加起来,我们有:
| param | formula | size (in bytes) |
|---|---|---|
| FFW params | d_model2 x ffw_multiplier x 3 (for SwiGLU gate, up, and down projections) x n_layers | 5,120 x 5,120 x 2.7 x 3 x 40 = 8.5e9 |
| Vocab params | 2 (input and output embeddings) x n_embeddings x d_model | 2 x 32,000 x 5,120 = 0.3e9 |
| Attention params | [2 (q and output) x d_model x n_heads x d_qkv + 2 (for k and v) x d_model x n_kv_heads x d_qkv] x n_layers | (2 x 5,120 x 40 x 128 + 2 x 5,120 x 40 x 128) x 40 = 4.2e9 |
| 参数 | 公式 | 大小(字节) |
|---|---|---|
| FFW 参数 | d_model2 x ffw_multiplier x 3(对应 SwiGLU 的 gate、up、down 三个投影)x n_layers | 5,120 x 5,120 x 2.7 x 3 x 40 = 8.5e9 |
| 词表参数 | 2(输入和输出 embedding)x n_embeddings x d_model | 2 x 32,000 x 5,120 = 0.3e9 |
| 注意力参数 | [2(q 和输出)x d_model x n_heads x d_qkv + 2(k 和 v)x d_model x n_kv_heads x d_qkv] x n_layers | (2 x 5,120 x 40 x 128 + 2 x 5,120 x 40 x 128) x 40 = 4.2e9 |
Adding these parameters up, we get 8.5e9 + 4.2e9 + 0.3e9 = 13e9 total parameters, just as expected. As we saw in the previous sections, during training we might store our parameters in bfloat16 with an optimizer state in float32. That may use around 100GB of memory. That pales in comparison to our gradient checkpoints, which can use several TBs.
把这些参数加起来,得到 8.5e9 + 4.2e9 + 0.3e9 = 13e9 个参数,和预期一致。如前面几节所述,训练时我们可能用 bfloat16 存参数、float32 存优化器状态,可能占用约 100GB 显存。与梯度检查点动辄几 TB 的占用相比,这就不值一提了。
How is inference different? During inference, we store one copy of our parameters, let’s say in bfloat16. That uses 26GB — and in practice we can often do much better than this with quantization. There’s no optimizer state or gradients to keep track of. Because we don’t checkpoint (keep activations around for the backwards pass), our activation footprint is negligible for both prefill (Particularly thanks to Flash Attention, which avoids materializing our attention matrix) and generate. If we prefill 8k tokens, a single activation only uses around 8,192 x 5,120 x 2 bytes = 80MB of memory. Longer prefills can be broken down into many smaller forward passes, so it’s not a problem for longer contexts either. Generation uses even fewer tokens than that, so activations are negligible.
推理有何不同? 推理时我们只存一份参数,假设用 bfloat16,占 26GB——而且实践中通过量化往往能做得远好于此。没有优化器状态或梯度需要维护。因为我们不做检查点(不为了反向传播保留激活),所以无论 prefill(尤其得益于 Flash Attention,它避免把注意力矩阵实体化)还是 generate,激活的占用都微不足道。如果 prefill 8k 个 token,单个激活只占用大约 8,192 x 5,120 x 2 bytes = 80MB 显存。更长的 prefill 可以拆成许多更小的前向传播,所以对长上下文也不是问题。generation 用到的 token 更少,激活更可忽略。
The main difference is the KV cache. These are the keys and value projections for all past tokens, bounded in size only by the maximum allowed sequence length. The total size for $$T$$ tokens is
最大的区别在于 KV cache。 它是所有过去 token 的 key 和 value 投影,其大小只受允许的最大序列长度限制。对 $$T$$ 个 token,总大小是
$$\text{KV cache size} = 2 \cdot \text{bytes per float} \cdot H \cdot K \cdot L \cdot T$$
where $$H$$ is the dimension of each head, $$K$$ is the number of KV heads, $$L$$ is the number of layers, and the 2 comes from storing both the keys and values.
其中 $$H$$ 是每个头的维度,$$K$$ 是 KV 头数,$$L$$ 是层数,2 来自同时存储 key 和 value。
This can get big very quickly, even with modest batch size and context lengths. For LLaMA-13B, a KV cache for a single 8192 sequence at bf16 is
它会很快变得非常大,即便 batch size 和上下文长度都不大。对 LLaMA-13B,单条 8192 长度序列在 bf16 下的 KV cache 是
$$8192\ (T) \times 40\ (K) \times 128\ (H) \times 40\ (L) \times 2\ (\text{bytes}) \times 2 = 6.7 \text{GB}$$
Just 4 of these exceed the memory usage of our parameters! To be clear, LLaMA 2 was not optimized for KV cache size at longer contexts (it isn’t always this bad, since usually $K$ is much smaller, as in LLaMA-3), but this is still illustrative. We cannot neglect these in memory or latency estimates.
仅仅 4 份这样的 KV cache 就超过了我们参数的显存占用! 说清楚一点,LLaMA 2 并没有针对长上下文下的 KV cache 大小做优化(情况并不总是这么糟,通常 $K$ 要小得多,比如 LLaMA-3),但这仍然很有说明性。在显存或延迟估算中,我们不能忽视它们。
Modeling throughput and latency for LLaMA 2-13B
为 LLaMA 2-13B 建模吞吐与延迟
Let’s see what happens if we try to perform generation perfectly efficiently at different batch sizes on 8xTPU v5es, up to the critical batch size (240) derived earlier for maximum theoretical throughput.
我们来看看,如果试图在 8xTPU v5e 上以不同 batch size 完美高效地做 generation(直到之前为最大理论吞吐推导出的临界 batch size 240),会发生什么。
| Batch Size | 1 | 8 | 16 | 32 | 64 | 240 |
|---|---|---|---|---|---|---|
| KV Cache Memory (GiB) | 6.7 | 53.6 | 107.2 | 214.4 | 428.8 | 1608 |
| Total Memory (GiB) | 32.7 | 79.6 | 133.2 | 240.4 | 454.8 | 1634 |
| Theoretical Step Time (ms) | 4.98 | 12.13 | 20.30 | 36.65 | 69.33 | 249.09 |
| Theoretical Throughput (tokens/s) | 200.61 | 659.30 | 787.99 | 873.21 | 923.13 | 963.53 |
| Batch Size | 1 | 8 | 16 | 32 | 64 | 240 |
|---|---|---|---|---|---|---|
| KV cache 显存(GiB) | 6.7 | 53.6 | 107.2 | 214.4 | 428.8 | 1608 |
| 总显存(GiB) | 32.7 | 79.6 | 133.2 | 240.4 | 454.8 | 1634 |
| 理论步时(ms) | 4.98 | 12.13 | 20.30 | 36.65 | 69.33 | 249.09 |
| 理论吞吐(tokens/s) | 200.61 | 659.30 | 787.99 | 873.21 | 923.13 | 963.53 |
8x TPU v5es gives us 128GiB of HBM, 6.5TiB/s of HBM bandwidth (0.82TiB/s each) and 1600TF/s of compute.
8x TPU v5e 给我们 128GiB 的 HBM、6.5TiB/s 的 HBM 带宽(每颗 0.82TiB/s)和 1600TF/s 的算力。
For this model, increasing the batch size does give us better throughput, but we suffer rapidly diminishing returns. We OOM beyond batch size 16, and need an order of magnitude more memory to go near 240. A bigger topology can improve the latency, but we’ve hit a wall on the per chip throughput.
对这个模型来说,增大 batch size 确实带来更好的吞吐,但收益迅速递减。超过 batch size 16 我们就 OOM 了,要接近 240 需要多一个数量级的显存。更大的拓扑可以改善延迟,但在每芯片吞吐上我们已经撞墙。
Let’s say we keep the total number of params the same, but magically make the KV cache 5x smaller (say, with 1 GMQA, which means we have 8 KV heads shared over the 40 Q heads — see next section for more details).
假设我们保持总参数量不变,但神奇地把 KV cache 缩小 5 倍(比如用 1 的 GMQA,也就是 8 个 KV 头共享覆盖 40 个 Q 头——详见下一节)。
| Batch Size | 1 | 8 | 16 | 32 | 64 | 240 |
|---|---|---|---|---|---|---|
| KV Cache Memory (GiB) | 1.34 | 10.72 | 21.44 | 42.88 | 85.76 | 321.6 |
| Total Memory (GiB) | 27.34 | 36.72 | 47.44 | 68.88 | 111.76 | 347.6 |
| Theoretical Step Time (ms) | 4.17 | 5.60 | 7.23 | 10.50 | 17.04 | 52.99 |
| Theoretical Throughput (tokens/s) | 239.94 | 1,429.19 | 2,212.48 | 3,047.62 | 3,756.62 | 4,529.34 |
| Batch Size | 1 | 8 | 16 | 32 | 64 | 240 |
|---|---|---|---|---|---|---|
| KV cache 显存(GiB) | 1.34 | 10.72 | 21.44 | 42.88 | 85.76 | 321.6 |
| 总显存(GiB) | 27.34 | 36.72 | 47.44 | 68.88 | 111.76 | 347.6 |
| 理论步时(ms) | 4.17 | 5.60 | 7.23 | 10.50 | 17.04 | 52.99 |
| 理论吞吐(tokens/s) | 239.94 | 1,429.19 | 2,212.48 | 3,047.62 | 3,756.62 | 4,529.34 |
With a smaller KV cache, we still have diminishing returns, but the theoretical throughput per chip continues to scale up to batch size 240. We can fit a much bigger batch of 64, and latency is also consistently better at all batch sizes. The latency, maximum throughput, and maximum batch size all improve dramatically! In fact, later LLaMA generations used this exact optimization — LLaMA-3 8B has 32 query heads and 8 KV heads (source).
KV cache 变小后,收益仍然递减,但每芯片理论吞吐能一路扩展到 batch size 240。我们可以装下大得多的 batch(64),而且所有 batch size 下的延迟都更稳定地更好。延迟、最大吞吐和最大 batch size 都大幅改善!事实上,后来的 LLaMA 各代就用了这个优化——LLaMA-3 8B 有 32 个 query 头和 8 个 KV 头(来源)。
Takeaway: In addition to params, the size of KV cache has a lot of bearing over the ultimate inference performance of the model. We want to keep it under control with a combination of architectural decisions and runtime optimizations.
结论: 除了参数之外,KV cache 的大小对模型的最终推理性能影响巨大。我们希望结合架构决策和运行时优化把它控制住。
Tricks for Improving Generation Throughput and Latency
提升生成吞吐与延迟的技巧
Since the original Attention is All You Need paper, many techniques have been developed to make the model more efficient, often targeting the KV cache specifically. Generally speaking, a smaller KV cache makes it easier to increase batch size and context length of the generation step without hurting latency, and makes life easier for the systems surrounding the Transformer (like request caching). Ignoring effects on quality, we may see:
自最初的 Attention is All You Need 论文以来,人们发展了许多让模型更高效的技术,往往专门针对 KV cache。一般来说,更小的 KV cache 让我们更容易在不损伤延迟的前提下增大 generation 步骤的 batch size 和上下文长度,也让 Transformer 周边的系统(比如请求缓存)更轻松。忽略对质量的影响,我们可能会看到:
Grouped multi-query attention (aka GMQA, GQA): We can reduce the number of KV heads, and share them with many Q heads in the attention mechanism. In the extreme case, it is possible to share a single KV head across all Q heads. This reduces the KV cache by a factor of the Q ratio over pure MHA, and it has been observed that the performance of models is relatively insensitive to this change.
Grouped multi-query attention(又名 GMQA、GQA): 我们可以减少 KV 头数,让多个 Q 头在注意力机制中共享它们。极端情况下,可以只用一个 KV 头被所有 Q 头共享。相比纯 MHA,这把 KV cache 缩小了 Q 之比那么多倍,而且人们观察到模型性能对这种改动相对不敏感。
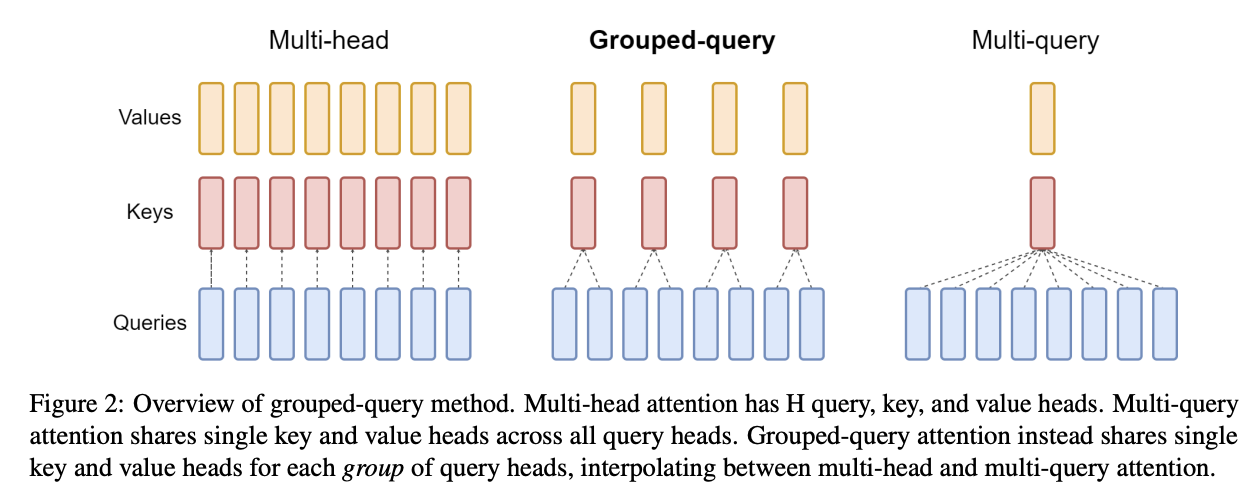
This also effectively increases the arithmetic intensity of the attention computation (see Question 4 in Section 4).
这实际上也提高了注意力计算的算术强度(见第 4 节的问题 4)。
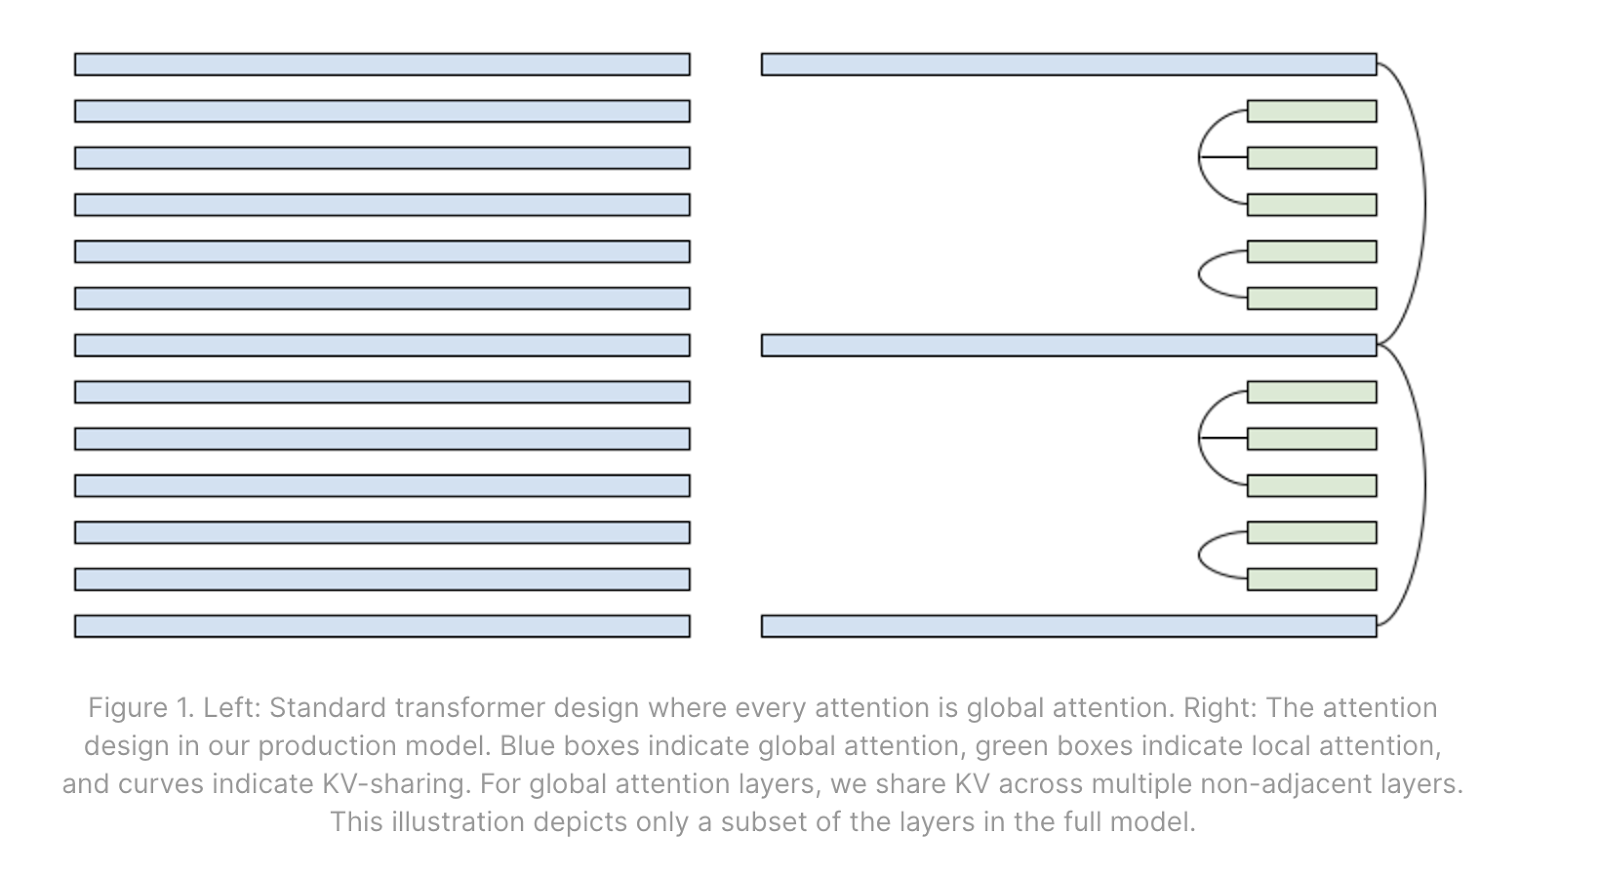
Mixing in some local attention layers: Local attention caps the context to a small to moderately sized max length. At training time and prefill time, this involves masking the attention matrix to a diagonal strip instead of a triangle. This effectively caps the size of the max length of the KV cache for the local layers. By mixing in some local layers into the model with some global layers, the KV cache is greatly reduced in size at contexts longer than the local window.
混入一些 local attention 层: 局部注意力把上下文限制在一个小到中等规模的最大长度内。在训练和 prefill 时,这相当于把注意力矩阵从三角形 mask 成一条对角带状。这实际上为局部层的 KV cache 长度封了顶。把一些局部层和一些全局层混合进模型后,当上下文超过局部窗口时,KV cache 会大幅缩小。
Sharing KVs across layers: The model can learn to share the same KV caches across layers in some pattern. Whilst this does reduce the KV cache size, and provide benefits in increasing batch size, caching, offline storage, etc., shared KV caches may need to be read from HBM multiple times, so it does not necessarily improve the step time.
跨层共享 KV: 模型可以学着按某种模式在不同层之间共享同一份 KV cache。虽然这确实缩小了 KV cache,并在增大 batch size、缓存、离线存储等方面带来好处,但共享的 KV cache 可能需要从 HBM 被读取多次,所以它未必能改善步时。
Quantization: Inference is usually less sensitive to the precision of parameters and KVs. By quantizing the parameters and KV cache (e.g. to int8, int4, fp8 etc.), we can save on memory bandwidth on both, decrease the batch size required to reach the compute roofline and save memory to run at bigger batch sizes. Quantization has the added advantage that even if the model was not trained with quantization it can often be applied post training.
量化: 推理通常对参数和 KV 的精度不那么敏感。把参数和 KV cache 量化(例如到 int8、int4、fp8 等),可以同时省下两者的显存带宽、降低达到计算 roofline 所需的 batch size,并省出显存以支持更大的 batch size。量化还有一个额外好处:即使模型训练时没有用量化,通常也能在训练后应用。
Using ragged HBM reads and Paged Attention: We allocated 8k of context for each KV cache in the calculations above but it is often not necessary to read the entire KV cache from memory — requests have a wide range of length distributions and don’t use the max context of the model, so we can often implement kernels (e.g. Flash Attention variants) that only read the non-padding part of the KV cache.
使用不规则的 HBM 读取与 Paged Attention: 上面的计算里我们为每份 KV cache 都分配了 8k 上下文,但通常没必要从显存里读取整份 KV cache——请求的长度分布很宽,并不会用满模型的最大上下文,所以我们往往可以实现只读取 KV cache 非 padding 部分的内核(例如 Flash Attention 的变体)。
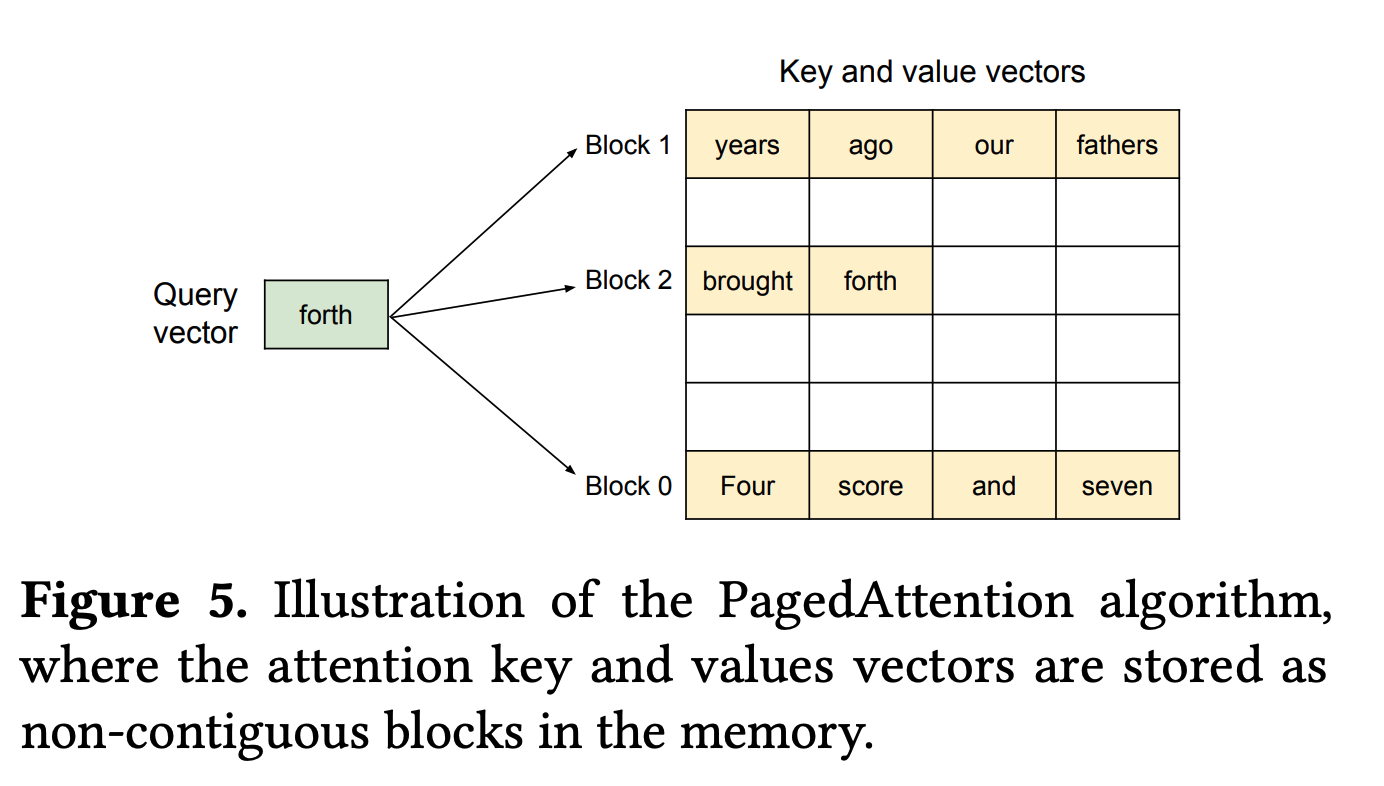
Paged Attention[paged] is a refinement upon this that stores KV caches in OS-style page tables and mostly avoids padding the KV caches altogether. This adds a lot of complexity but means every batch only uses as much memory as it needs. This is a runtime optimization, so again it is indifferent to architecture.
Paged Attention[paged] 是这一思路的进一步精化,它把 KV cache 存在操作系统风格的页表里,基本完全避免了给 KV cache 做 padding。这增加了很多复杂度,但意味着每个 batch 只用它真正需要的显存。这是一种运行时优化,所以同样与架构无关。
Big Picture: All told, these KV cache optimizations can reduce KV cache sizes by over an order of magnitude compared to a standard MHA Transformer. This can lead to an order-of-magnitude improvement in the overall cost of the Transformer.
大局观: 总的来说,相比标准 MHA Transformer,这些 KV cache 优化可以把 KV cache 大小缩小一个数量级以上。这能让 Transformer 的总体成本改善一个数量级。
Distributing Inference Over Multiple Accelerators
把推理分布到多颗加速器上
So far we’ve handwaved how we’re scaling beyond a single chip. Following Section 5, let’s explore the different strategies available to us and their tradeoffs. As always, we will look at prefill and generation separately.
到目前为止,我们对如何扩展到单芯片之外都只是含糊带过。沿用第 5 节,我们来探讨可用的各种策略及其取舍。和往常一样,我们会分别看 prefill 和 generation。
Prefill
Prefill
From a roofline standpoint, prefill is almost identical to training and almost all the same techniques and tradeoffs apply — model (Megatron) parallelism, sequence sharding (for sufficiently long context), pipelining, even FSDP are all viable! You just have to keep the KVs kicking around so you can do generation later. As in training, increasing the number of chips gives us access to more FLOPs/s (for potentially lower TTFT), but adds communication overhead (potentially reducing throughput per chip).
从 roofline 的角度看,prefill 与训练几乎完全相同,几乎所有相同的技术和取舍都适用——模型(Megatron)并行、序列分片(上下文足够长时)、流水线,甚至 FSDP 都可行!你只需要把 KV 保留下来,以便之后做 generation。和训练一样,增加芯片数让我们获得更多 FLOPs/s(可能降低 TTFT),但会增加通信开销(可能降低每芯片吞吐)。
The general rule for sharding prefill: here’s a general set of rules for prefill. We’ll assume we’re doing prefill on a single sequence only (no batch dimension):
prefill 分片的一般规则: 下面是 prefill 的一套通用规则。我们假设只对单条序列做 prefill(没有 batch 维度):
- Model sharding: We typically do some amount of model parallelism first, up to the point we become ICI-bound. As we saw in Section 5, this is around $F / 2200$ for 1 axis (usually around 4-8 way sharding).
- Sequence parallelism: Beyond this, we do sequence parallelism (like data parallelism but sharding across the sequence dimension). While sequence parallelism introduces some extra communication in attention, it is typically fairly small at longer contexts. As with training, we can overlap the communication and computation (using collective matmuls for Megatron and ring attention respectively).
- 模型分片: 我们通常先做一定量的模型并行,直到变成 ICI 受限。如第 5 节所见,对 1 条轴大约是 $F / 2200$(通常是 4–8 路分片)。
- 序列并行: 在此之上,我们做序列并行(类似数据并行,但沿序列维度分片)。虽然序列并行会在注意力中引入一些额外通信,但在较长上下文下它通常相当小。与训练一样,我们可以让通信与计算重叠(分别对 Megatron 用 collective matmuls、对 ring attention 用相应的方式)。
Takeaway: during prefill, almost any sharding that can work during training can work fine. Do model parallelism up to the ICI bound, then do sequence parallelism.
结论: 在 prefill 阶段,几乎任何训练时能用的分片都能正常工作。先做模型并行直到 ICI 界限,然后做序列并行。
Generation
Generation
Generation is a more complicated beast than prefill. For one thing, it is harder to get a large batch size because we need to batch many requests together. Latency targets are lower. Together, these mean we are typically more memory-bound and more sensitive to communication overhead, which restrict our sharding strategies:
generation 比 prefill 更复杂。首先,因为需要把许多请求拼批,拿到大 batch size 更难;延迟目标也更低。两者合起来意味着我们通常更受显存限制、对通信开销更敏感,这限制了我们的分片策略:
- FSDP is impossible: since we are memory-bound in loading our parameters and KV caches from HBM to the MXU, we do not want to move them via ICI which is orders of magnitudes slower than HBM. We want to move activations rather than weights. This means methods similar to FSDP are usually completely unviable for generation. (Accidentally leaving it on after training is an easy and common way to have order of magnitude regressions)
- FSDP 不可行: 由于把参数和 KV cache 从 HBM 加载到 MXU 时我们是显存受限的,我们不希望通过比 HBM 慢好几个数量级的 ICI 来搬运它们。我们要搬运的是激活,而不是权重。 这意味着类似 FSDP 的方法通常完全不适合 generation。(训练后不小心忘了关掉它,是导致性能退化一个数量级的常见且容易犯的错。)
- There is no reason to do data parallelism: pure data parallelism is unhelpful because it replicates our parameters and doesn’t help us load parameters faster. You’re better off spinning up multiple copies of the model instead. (By this we mean, spin up multiple servers with copies of the model at a smaller batch size. Data parallelism at the model level is strictly worse.)
- 没有理由做数据并行: 纯数据并行没有帮助,因为它会复制我们的参数,而不能让我们更快地加载参数。更好的做法是起多份模型副本。(这里指的是:起多个服务器,每个都有模型副本、用更小的 batch size。模型层面的数据并行严格来说更差。)
- No sequence = no sequence sharding. Good luck sequence sharding.
- 没有序列就没有序列分片。 序列分片祝你好运。
This mostly leaves us with variants of model sharding for dense model generation. As with prefill, the simplest thing we can do is simple model parallelism (with activations fully replicated, weights fully sharded over hidden dimension for the MLP) up to 4-8 ways when we become ICI bound. However, since we are often memory bandwidth bound, we can actually go beyond this limit to improve latency!
于是对稠密模型的 generation,我们基本只剩下各种模型分片的变体。 和 prefill 一样,最简单的做法是朴素的模型并行(激活完全复制,MLP 的权重沿隐藏维完全分片),最多做到 4–8 路,直到变成 ICI 受限。不过,由于我们常常是显存带宽受限,其实可以越过这个界限来改善延迟!
Note on ICI bounds for generation: during training we want to be compute-bound, so our rooflines look at when our ICI comms take longer than our FLOPs. However, during generation, if we’re memory bandwidth bound by parameter loading, we can increase model sharding beyond this point and improve latency at a minimal throughput cost (in terms of tokens/sec/chip). More model sharding gives us more HBM to load our weights over, and our FLOPs don’t matter. (In the sense that FLOPs time isn’t bottlenecking us, so the thing we need to worry about is ICI time exceeding parameter loading time.) Let’s look at how much model parallelism we can do before it becomes the bottleneck.
关于 generation 的 ICI 界限: 训练时我们希望计算受限,所以我们的 roofline 看的是 ICI 通信什么时候比 FLOPs 更久。然而在 generation 时,如果我们是因加载参数而显存带宽受限,就可以把模型分片推到超过这个点,以极小的吞吐代价(以 tokens/sec/chip 计)改善延迟。更多的模型分片给我们更多 HBM 来加载权重,而 FLOPs 无关紧要。(意思是 FLOPs 时间不是瓶颈,所以我们需要担心的是 ICI 时间超过参数加载时间。)我们来看看在变成瓶颈之前能做多少模型并行。
$$\begin{align*}T_\text{HBM comms} = \frac{2DF}{Y \cdot W_\text{hbm}} && T_\text{ICI comms} = \frac{2BD}{W_\text{ici}}\end{align*}$$
$$T_\text{ICI comms} > T_\text{HBM comms} \rightarrow \frac{W_\text{hbm}}{W_\text{ici}} > \frac{F}{Y \cdot B} \rightarrow Y > F / (B \cdot \beta)$$
where $\beta = W_\text{hbm} / W_\text{ici}$. This number is usually around 8 for TPU v5e and TPU v6e. That means e.g. if $F$ is 16,384 and $B$ is 32, we can in theory do model parallelism up to 16384 / (32 * 8) = 64 ways without a meaningful hit in throughput. This assumes we can fully shard our KV caches 64-ways which is difficult: we discuss this below.
其中 $\beta = W_\text{hbm} / W_\text{ici}$。对 TPU v5e 和 TPU v6e,这个数通常在 8 左右。也就是说,例如 $F$ 为 16,384、$B$ 为 32 时,理论上我们最多可以做到 16384 / (32 * 8) = 64 路模型并行,而对吞吐没有明显损失。这假设我们能 64 路完全分片 KV cache,而这很难:我们下面会讨论。
For the attention layer, we also model shard attention $$W_Q$$ and $$W_O$$ over heads Megatron style. The KV weights are quite small, and replicating them is often cheaper than sharding beyond $K$-way sharding.
对注意力层,我们也按 Megatron 风格把头维度分片给注意力的 $$W_Q$$ 和 $$W_O$$。KV 权重相当小,超过 $K$ 路分片时,复制它们往往比继续分片更便宜。
Takeaway: our only options during generation are variants of model parallelism. We aim to move activations instead of KV caches or parameters, which are larger. When our batch size is large, we do model parallelism up to the FLOPs-ICI bound ($F / \alpha$). When our batch size is smaller, we can improve latency by model sharding more (at a modest throughput cost). When we want to model shard more ways than we have KV heads, we can shard our KVs along the batch dimension as well.
结论: generation 时我们唯一的选择就是各种模型并行的变体。我们的目标是搬运激活,而不是更大的 KV cache 或参数。当 batch size 较大时,我们做到 FLOPs-ICI 界限($F / \alpha$)为止。当 batch size 较小时,我们可以通过更多模型分片来改善延迟(吞吐略有代价)。当我们想要的分片路数超过 KV 头数时,还可以沿 batch 维度分片 KV。
Sharding the KV cache
分片 KV cache
We also have an additional data structure that needs to be sharded — the KV cache. Again, we almost always prefer to avoid replicating the cache, since it is the primary source of attention latency. To do this, we first Megatron-shard the KVs along the head dimension. This is limited to $K$-way sharding, so for models with a small number of heads, we shard the head dimension as much as possible and then shard along the batch dimension, i.e. $\text{KV}[2, B_Z, S, K_Y, H]$. This means the KV cache is completely distributed.
我们还有一个额外的数据结构需要分片——KV cache。 再说一次,由于 cache 是注意力延迟的主要来源,我们几乎总是倾向于避免复制它。为此,我们先把 KV 沿头维度做 Megatron 分片。这受限于 $K$ 路分片,所以对头数很少的模型,我们尽量分片头维度,然后沿 batch 维度继续分片,即 $\text{KV}[2, B_Z, S, K_Y, H]$。这意味着 KV cache 被完全分布化。
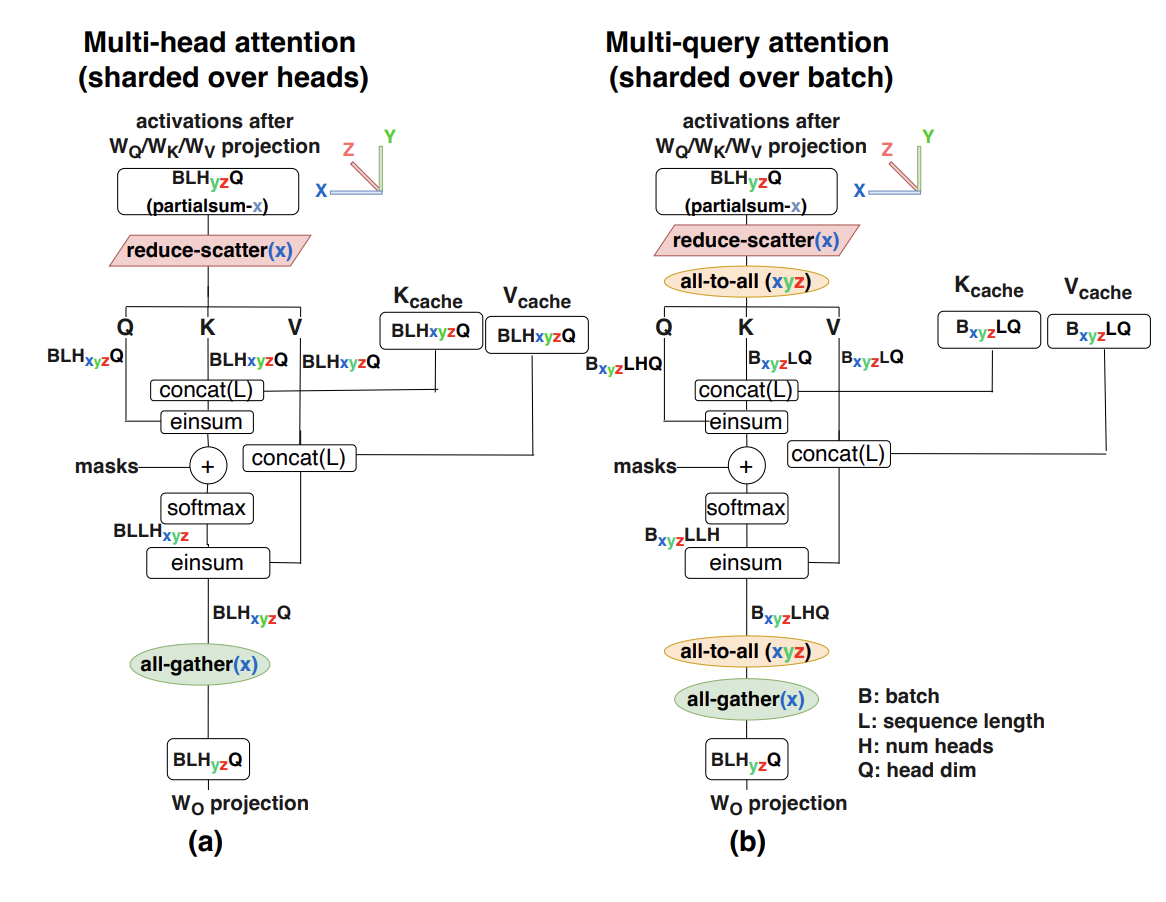
The cost of this is two AllToAlls every attention layer — one to shift the Q activations to the batch sharding so we can compute attention with batch sharding, and one to shift the batch sharded attention output back to pure model sharded.
代价是每个注意力层要做两次 AllToAll——一次把 Q 激活搬到 batch 分片布局,以便用 batch 分片计算注意力;一次把 batch 分片的注意力输出搬回纯模型分片布局。
Here's the full algorithm!
下面是完整算法!
Here we’ll write out the full attention algorithm with model parallelism over both $Y$ and $Z$. I apologize for using $K$ for both the key tensor and the KV head dimension. Let $M=N/K$.
这里我们写出同时在 $Y$ 和 $Z$ 上做模型并行的完整注意力算法。抱歉我用 $K$ 同时表示 key 张量和 KV 头维度。令 $M=N/K$。
- X[B, D] = … (existing activations, unsharded from previous layer)
- K[BZ, S, KY, H], V[BZ, S, KY, H] = … (existing KV cache, batch sharded)
- Q[B, NYZ, H] = X[B, D] * WQ[D, NYZ, H]
- Q[BZ, NY, H] = AllToAllZ->B(Q[B, NYZ, H])
- Q[BZ, KY, M, H] = Reshape(Q[BZ, NY, H])
- O[BZ, S, KY, M] = Q[BZ, KY, M, H] *H K[BZ, S, KY, H]
- O[BZ, S, KY, M] = SoftmaxS(O[BZ, S, KY, M])
- O[BZ, KY, M, H] = O[BZ, S, KY, M] *S V[BZ, S, KY, H]
- O[B, KY, MZ, H] = AllToAllZ->M(O[BZ, KY, M, H])
- O[B, NYZ, H] = Reshape(O[B, KY, MZ, H])
- X[B, D] {UYZ} = WO[NYZ, H, D] *N,H O[B, NYZ, H]
- X[B, D] = AllReduce(X[B, D] { UYZ})
- X[B, D] = …(已有激活,来自上一层的未分片状态)
- K[BZ, S, KY, H], V[BZ, S, KY, H] = …(已有 KV cache,按 batch 分片)
- Q[B, NYZ, H] = X[B, D] * WQ[D, NYZ, H]
- Q[BZ, NY, H] = AllToAllZ->B(Q[B, NYZ, H])
- Q[BZ, KY, M, H] = Reshape(Q[BZ, NY, H])
- O[BZ, S, KY, M] = Q[BZ, KY, M, H] *H K[BZ, S, KY, H]
- O[BZ, S, KY, M] = SoftmaxS(O[BZ, S, KY, M])
- O[BZ, KY, M, H] = O[BZ, S, KY, M] *S V[BZ, S, KY, H]
- O[B, KY, MZ, H] = AllToAllZ->M(O[BZ, KY, M, H])
- O[B, NYZ, H] = Reshape(O[B, KY, MZ, H])
- X[B, D] {UYZ} = WO[NYZ, H, D] *N,H O[B, NYZ, H]
- X[B, D] = AllReduce(X[B, D] { UYZ})
This is pretty complicated but you can see generally how it works. The new comms are modestly expensive since they operate on our small activations, while in return we save a huge amount of memory bandwidth loading the KVs (which are stationary).
这相当复杂,但你能大致看懂它是怎么工作的。新增的通信开销不算大,因为它们作用在我们很小的激活上;作为回报,我们在加载(作为驻留数据的)KV 时省下了大量显存带宽。
- Sequence sharding: If the batch size is too small, or the context is long, we can sequence shard the KV cache. Again, we pay a collective cost in accumulating the attention across shards here. First we need to AllGather the Q activations, and then accumulate the KVs in a similar fashion to Flash Attention.
- 序列分片: 如果 batch size 太小、或上下文很长,我们可以对 KV cache 做序列分片。同样,跨分片累加注意力需要付出集合通信代价。我们首先需要 AllGather Q 激活,然后以类似 Flash Attention 的方式累加 KV。
Designing an Effective Inference Engine
设计一个高效的推理引擎
So far we’ve looked at how to optimize and shard the individual prefill and generate operations efficiently in isolation. To actually use them effectively, we need to design an inference engine which can feed these two operations at a point of our choosing on the latency/throughput Pareto frontier.
到目前为止,我们孤立地看了如何高效地优化和分片单独的 prefill 与 generate 操作。要真正高效地使用它们,我们需要设计一个推理引擎,能在延迟 / 吞吐 Pareto 前沿上我们选定的某一点上给这两个操作供数。
The simplest method is simply to run a batch of prefill, then a batch of generations:
最简单的方法是先跑一批 prefill,再跑一批 generation:
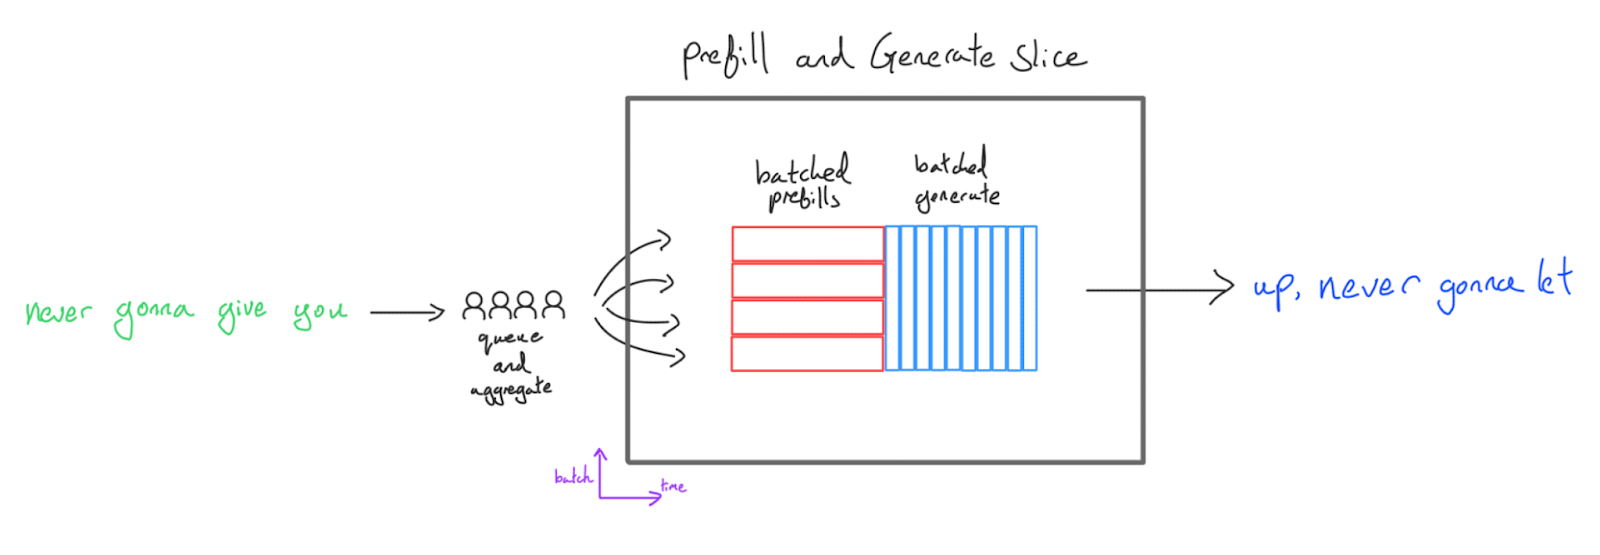
This is easy to implement and is the first inference setup in most codebases, but it has multiple drawbacks:
这很容易实现,也是大多数代码库里的第一版推理方案,但它有多个缺点:
- Latency is terrible. We couple the prefill and generate batch size. Time to first token (TTFT) is terrible at big prefill batch sizes — you need to finish all prefills before any users can see any tokens. Generate throughput is terrible at small batch sizes.
- We block shorter generations on longer ones. Many sequences will finish before others, leaving empty batch slots during generation, hurting generate throughput further. The problem exacerbates as batch size and generation length increases.
- Prefills are padded. Prefills are padded to the longest sequence and we waste a lot of compute. There are solutions for this, but historically XLA made it quite difficult to skip these FLOPs. Again this becomes worse the bigger the batch size and prefill sequence length.
- We’re forced to share a sharding between prefill and generation. Both prefill and generate live on the same slice, which means we use the same topology and shardings (unless you keep two copies of the weights) for both and is generally unhelpful for performance e.g. generate wants a lot more model sharding.
- 延迟很差。 我们把 prefill 和 generate 的 batch size 绑在了一起。prefill batch 很大时,首 token 时间(TTFT)很糟——必须等所有 prefill 都做完,用户才能看到任何 token。batch 很小时,generate 吞吐又很糟。
- 短的生成会被长的生成堵住。 很多序列会比其他序列先结束,在 generation 期间留下空的 batch 槽位,进一步伤害 generate 吞吐。batch size 和生成长度越大,问题越严重。
- prefill 要 padding。 prefill 会被 padding 到最长的序列,浪费大量算力。对此有解决方案,但历史上 XLA 很难跳过这些 FLOPs。同样,batch size 和 prefill 序列长度越大,问题越严重。
- 被迫让 prefill 和 generation 共用一套分片。 prefill 和 generate 都在同一个 slice 上,意味着两者使用相同的拓扑和分片(除非你保留两份权重),这通常不利于性能,比如 generate 想要多得多的模型分片。
Therefore this method is only recommended for edge applications (which usually only cares about serving a single user and using hardware with less FLOPs/byte) and rapid iteration early in the lifecycle of a Transformer codebase (due to its simplicity).
因此,这个方法只推荐用于边缘应用(它们通常只关心服务单个用户、使用 FLOPs/byte 较低的硬件),以及在 Transformer 代码库生命周期的早期快速迭代(因为它简单)。
A slightly better approach involves performing prefill at batch size 1 (where it is compute-bound but has reasonable latency) but batch multiple requests together during generation:
稍好一点的做法是在 batch size 1 下做 prefill(此时它计算受限、延迟也合理),而在 generation 时把多个请求拼批:
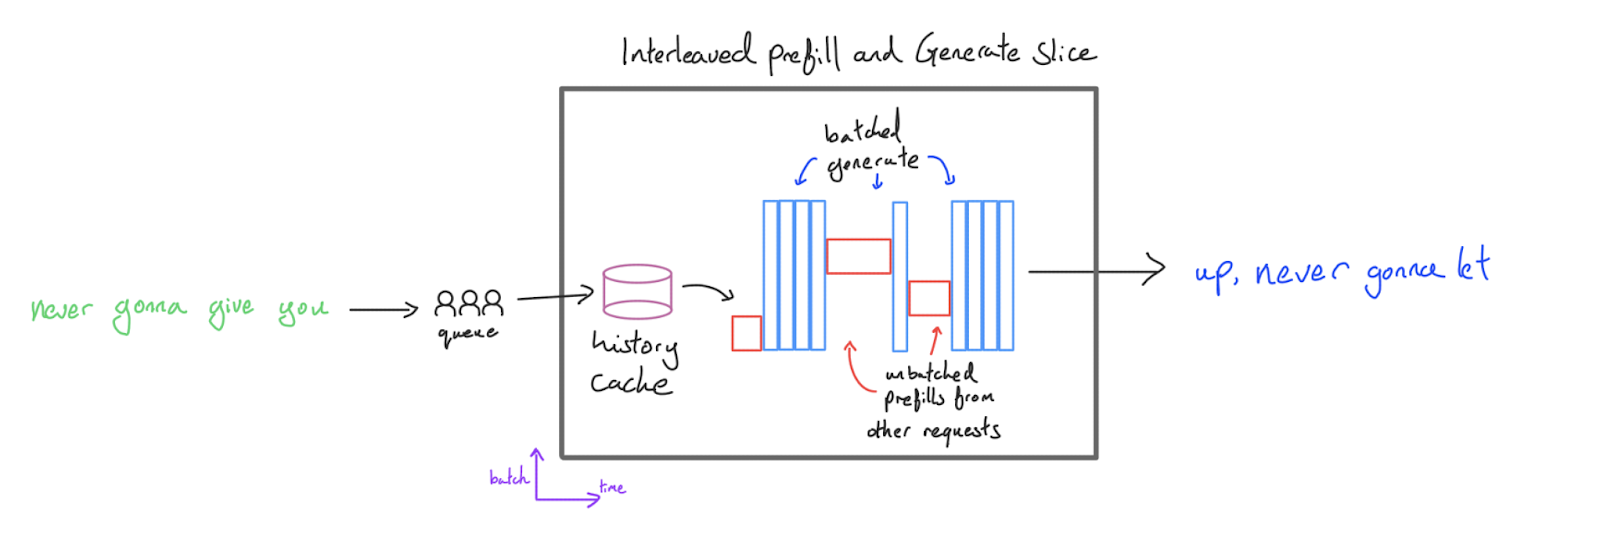
This will avoid wasted TTFT from batched prefill while keeping generation throughput high. We call this an interleaved configuration, since we “interleave” prefill and generation steps. This is very powerful for bulk generation applications like evaluations where throughput is the main goal. The orchestrator can be configured to prioritise prefill the moment any generation slots open up, ensuring high utilisation even for very large generation batch sizes. We can also avoid padding our prefill to the maximum length, since it isn’t batched with another request.
这避免了大 batch prefill 带来的 TTFT 浪费,同时保持 generation 吞吐较高。我们称之为 interleaved(交错) 配置,因为我们把 prefill 和 generation 步骤「交错」起来。这对批量生成类应用(比如以吞吐为主要目标的评测)非常强大。编排器可以配置成:一旦有任何 generation 槽位空出来就优先做 prefill,从而即便 generation batch size 很大也能保证高利用率。我们也可以避免把 prefill padding 到最大长度,因为它不和别的请求拼批。
The main disadvantage is that when the server is performing a prefill, the generation of all other requests pauses since all the compute resources will be consumed by the prefill. User A whose response is busy decoding will be blocked by user B whose prefill is occurring. This means even though TTFT has improved, the token generation will be jittery and slow on average, which is not a good user experience for many applications — other user’s prefills are on the critical path of the overall latency of a request.
主要缺点是,当服务器在做 prefill 时,所有其他请求的 generation 都会暂停,因为全部算力都会被这次 prefill 占用。正在解码的用户 A 会被正在 prefill 的用户 B 堵住。这意味着即使 TTFT 改善了,token 生成平均来看依然会抖动且缓慢,对很多应用来说用户体验并不好——别人的 prefill 落在了一个请求整体延迟的关键路径上。
To get around this, we separate decode and prefill. While Transformer inference can be done on one server, it is often better from a latency standpoint to execute the two different tasks on two sets of TPUs/GPUs. Prefill servers generate KV caches that get sent across the network to the generate servers, which batch multiple caches together and generate tokens for each of them. We call this “disaggregated” serving.
为了解决这个问题,我们把 decode 和 prefill 拆开。虽然 Transformer 推理可以在一台服务器上完成,但从延迟角度看,把这两个不同任务放到两组 TPU/GPU 上执行往往更好。prefill 服务器生成 KV cache,通过网络发送给 generate 服务器,后者把多份 cache 拼批并逐个生成 token。我们称之为 「分离式」(disaggregated) 服务。
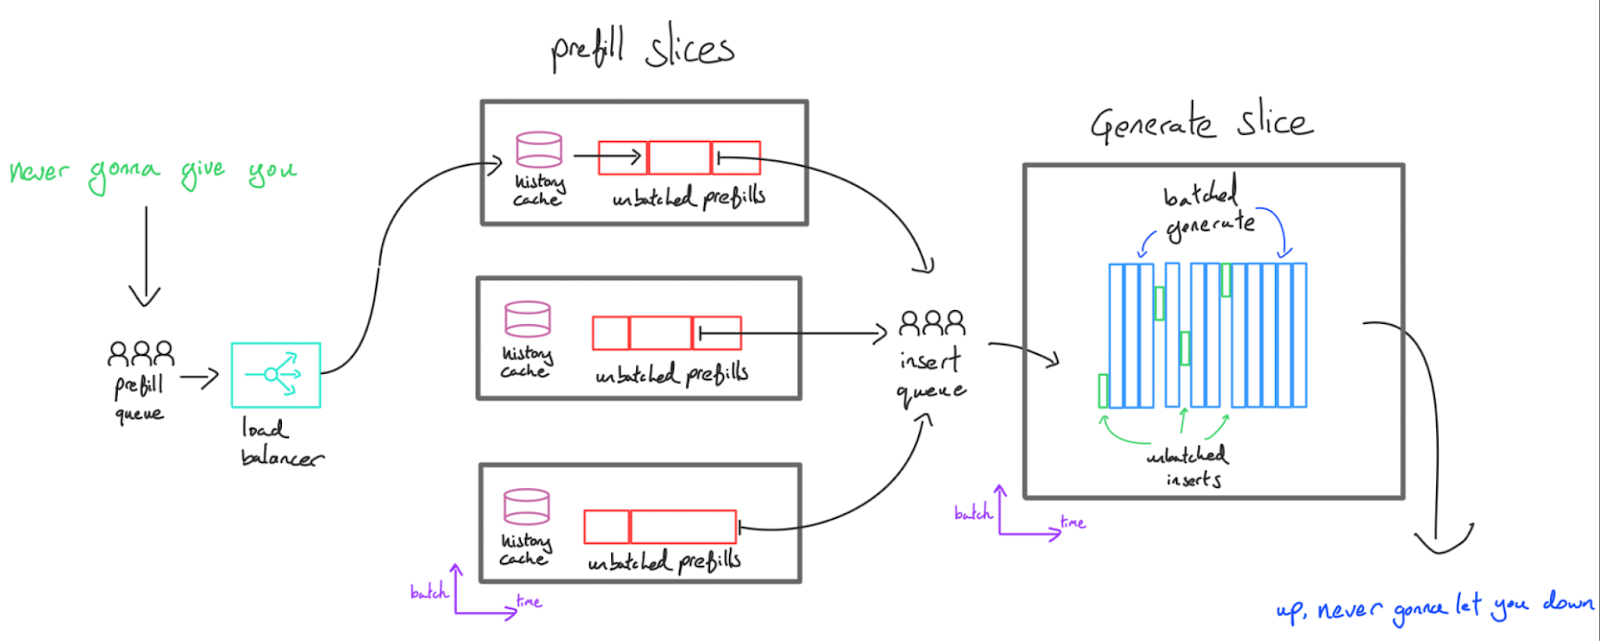
This provides a few advantages:
这带来几个好处:
- Low latency at scale: A user’s request never blocks on another user’s, except if there is insufficient prefill capacity. The request should be immediately prefilled, then sent to the generation server, then immediately slotted into the generation buffer. If we expect many concurrent requests to come in, we can scale the number of prefill servers independently from the number of generate servers so users are not left in the prefill queue for an extended period of time.
- 规模化下的低延迟:用户的请求永远不会被另一个用户的请求堵住,除非 prefill 容量不足。请求应当被立即 prefill,然后送到 generation 服务器,再立即放入 generation 缓冲区。如果我们预期会有很多并发请求,可以独立于 generate 服务器数量来扩缩 prefill 服务器数量,这样用户就不会长时间滞留在 prefill 队列里。
- Specialization: Quite often, the latency-optimal parameter sharding strategy/hardware topology for prefill and generate is quite different (for instance, more model parallelism is useful for generate but not prefill). Constraining the two operations to use the same sharding hurts the performance of both, and having two sets of weights uses memory. Also, by moving prefill onto its own server, it doesn’t need to hold any KV caches except the one it’s currently processing. That means we have a lot more memory free for history caching (see the next section) or optimizing prefill latency.
- 专业化: 很多时候,prefill 和 generate 的延迟最优参数分片策略 / 硬件拓扑相当不同(例如更多模型并行对 generate 有用、对 prefill 没用)。强行让两个操作共用一套分片会同时损害两者性能,而保留两份权重又要占显存。此外,把 prefill 移到自己的服务器上后,它除了当前正在处理的那份之外不需要持有任何 KV cache。这意味着我们有更多空闲显存用于历史缓存(见下一节)或优化 prefill 延迟。
One downside is that the KV cache now needs to be shifted across the network. This is typically acceptable but again provides a motivation for reducing KV cache size.
一个缺点是 KV cache 现在需要跨网络搬运。这通常可以接受,但同样构成了缩小 KV cache 大小的动机。
Takeaway: for latency-sensitive, high-throughput serving, we typically have to separate prefill and generation into separate servers, with prefill operating at batch 1 and generation batching many concurrent requests together.
结论: 对延迟敏感、高吞吐的服务,我们通常必须把 prefill 和 generation 拆到不同服务器上,prefill 以 batch 1 运行,而 generation 把许多并发请求拼批。
Continuous batching
Continuous batching
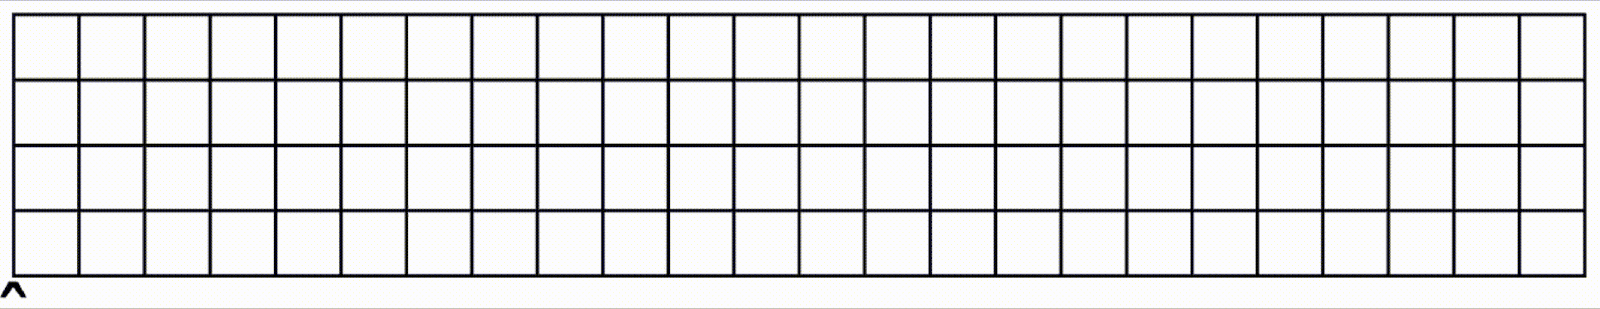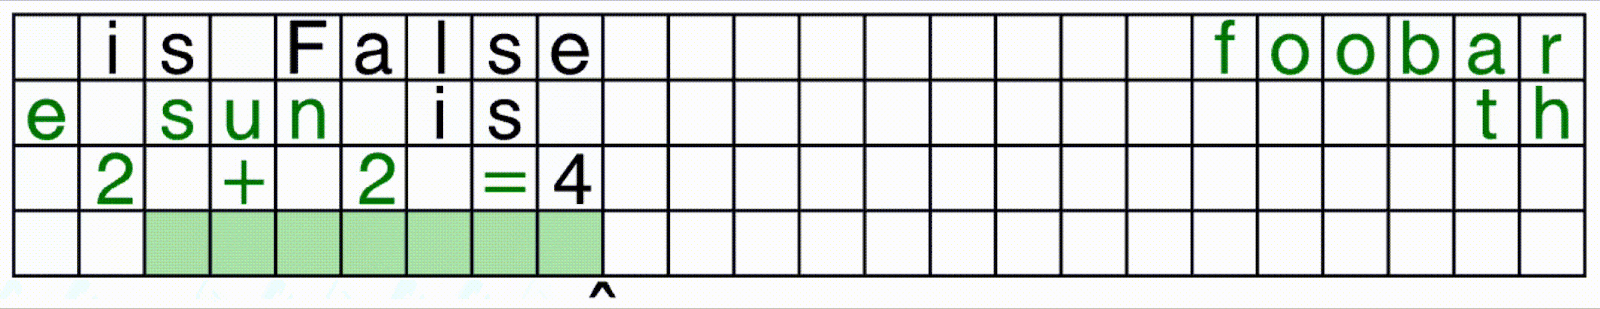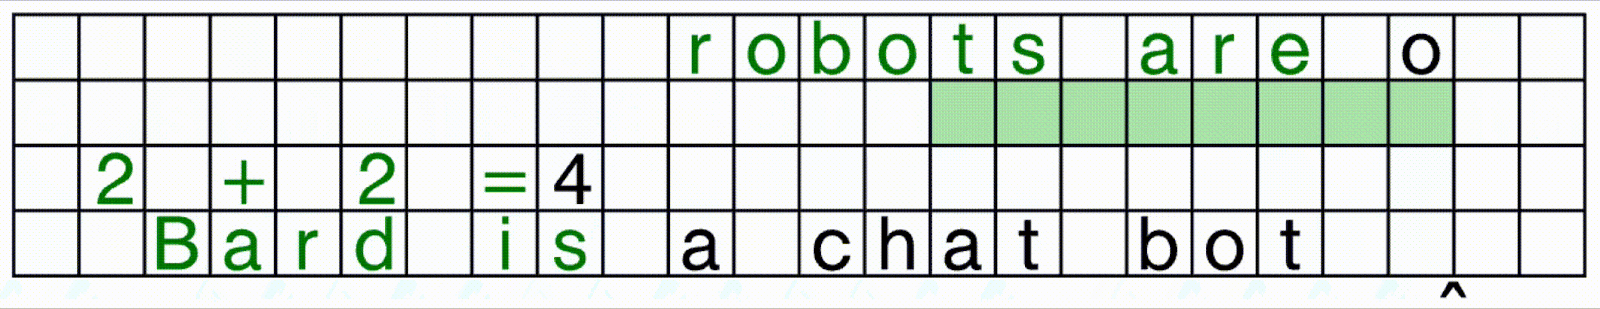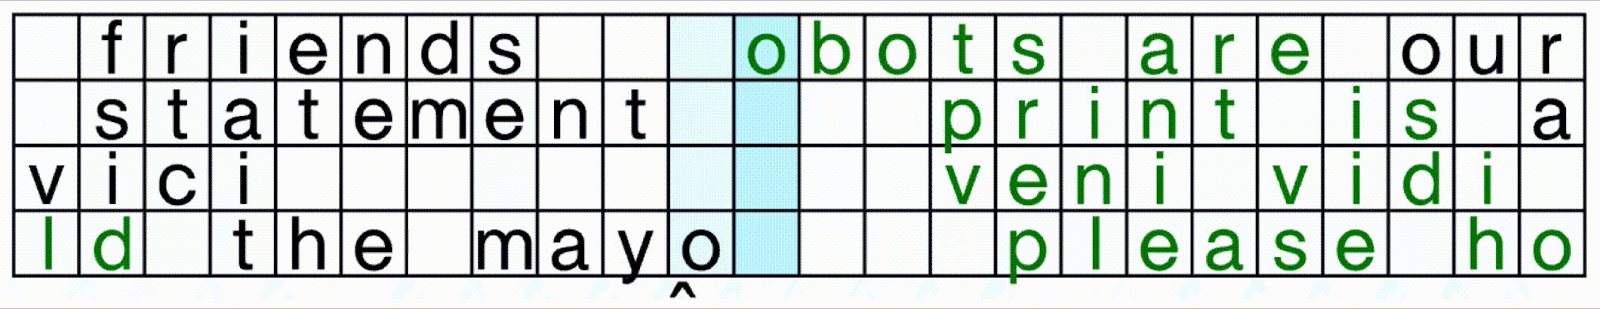
Problem (2) above motivates the concept of continuous batching. We optimize and compile:
上面的问题 (2) 引出了 continuous batching(连续批处理) 的概念。我们优化并编译:
- A prefill function that handles variable context lengths and inserts results into a KV buffer with some maximum batch size and context length/number of pages.
- A generate function which takes in the KV cache, and performs the generation step for all currently active requests.
- 一个 prefill 函数,处理可变的上下文长度,并把结果插入一个具有最大 batch size 和上下文长度 / 页数的 KV 缓冲区。
- 一个 generate 函数,接收 KV cache,并为当前所有活跃请求执行 generation 步骤。
We then combine these functions with an orchestrator which queues the incoming requests, calls prefill and generate depending on the available generate slots, handles history caching (see next section) and streams the tokens out.
然后我们把这些函数与一个编排器结合起来,由它把到来的请求排队、根据可用的 generate 槽位调用 prefill 和 generate、处理历史缓存(见下一节),并把 token 流式输出。
Prefix caching
Prefix caching
Since prefill is expensive and compute-bound (giving us less headroom), one of the best ways to reduce its cost is to do less of it. Because LLMs are autoregressive, the queries [“I”, “like”, “dogs”] and [“I”, “like”, “cats”] produce KV caches that are identical in the first two tokens. What this means is that, in principle, if we compute the “I like dogs” cache first and then the “I like cats” cache, we only need to do 1 / 3 of the compute. We can save most of the work by reusing the cache. This is particularly powerful in a few specific cases:
由于 prefill 昂贵且计算受限(留给我们的余地更小),降低其成本的最好办法之一就是少做 prefill。因为 LLM 是自回归的,查询 [“I”, “like”, “dogs”] 和 [“I”, “like”, “cats”] 产生的 KV cache 在前两个 token 上是完全相同的。这意味着,原则上如果我们先算了「I like dogs」的 cache,再算「I like cats」的 cache,就只需要做 1/3 的计算。通过复用 cache,我们能省掉大部分工作。这在几种特定场景下尤其强大:
- Chatbots: most chatbot conversations involve a back-and-forth dialog that strictly appends to itself. This means if we can save the KV caches from each dialog turn, we can skip computation for all but the newest tokens.
- Few-shot prompting: if we have any kind of few-shot prompt, this can be saved and reused for free. System instructions often have this form as well.
- 聊天机器人:大多数聊天机器人对话都是一来一回、严格向后追加的。这意味着如果能把每一轮对话的 KV cache 存下来,除了最新的 token 之外,其余计算都能跳过。
- Few-shot prompting:任何形式的 few-shot prompt 都可以被保存并免费复用。系统指令往往也是这种形式。
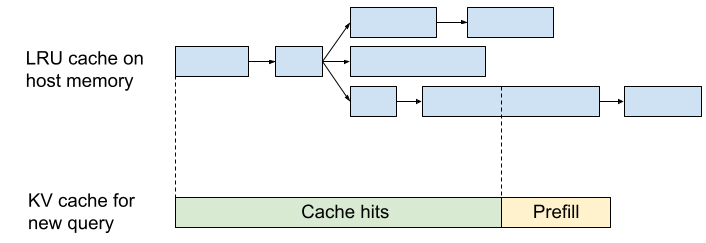
The only reason this is hard to do is memory constraints. As we’ve seen, KV caches are big (often many GB), and for caching to be useful we need to keep them around until a follow-up query arrives. Typically, any unused HBM on the prefill servers can be used for a local caching system. Furthermore, accelerators usually have a lot of memory on their CPU hosts (e.g. a 8xTPUv5e server has 128GiB of HBM, but around 450GiB of Host DRAM). This memory is much slower than HBM — too slow to do generation steps usually — but is fast enough for a cache read. In practice:
这么做唯一的难点在于显存约束。如我们所见,KV cache 很大(常常有好几 GB),而缓存要有用,就必须把它保留到后续查询到来为止。通常 prefill 服务器上任何未使用的 HBM 都可以用来做本地缓存系统。此外,加速器的 CPU 主机通常有很多内存(例如一台 8xTPUv5e 服务器有 128GiB HBM,但主机 DRAM 约有 450GiB)。这种内存比 HBM 慢得多——通常慢到不足以做 generation 步骤——但足以做一次缓存读取。实践中:
- Because the KV cache is local to the set of TPUs that handled the initial request, we need some form of affinity routing to ensure follow-up queries arrive at the same replica. This can cause issues with load balancing.
- A smaller KV cache is helpful (again) — it enables us to save more KV caches in the same amount of space, and reduce read times.
- The KV cache and their lookups can be stored quite naturally in a tree or trie. Evictions can happen on an LRU basis.
- 因为 KV cache 是局部的、属于处理初始请求的那组 TPU,我们需要某种亲和路由,确保后续查询落到同一个副本上。这可能给负载均衡带来麻烦。
- 更小的 KV cache(再次)有帮助——它让我们在同样的空间里存下更多 KV cache,并缩短读取时间。
- KV cache 及其查找天然可以存在一棵树或 trie 里。淘汰可以按 LRU 进行。
Let’s look at an implementation: JetStream
看一个实现:JetStream
Google has open-sourced a library that implements this logic called JetStream. The server has a set of “prefill engines” and “generate engines”, usually on different TPU slices, which are orchestrated by a single controller. Prefill happens in the “prefill thread”, while generation happens in the “generate thread”. We also have a “transfer thread” that orchestrates copying the KV caches from the prefill to generate slices.
Google 开源了一个实现这套逻辑的库,叫 JetStream。服务器有一组「prefill engines」和「generate engines」,通常位于不同的 TPU slice 上,由一个 controller 编排。prefill 发生在「prefill 线程」里,generation 发生在「generate 线程」里。我们还有一个「transfer 线程」,负责编排把 KV cache 从 prefill slice 拷贝到 generate slice。
The Engine interface (implemented here) is a generic interface that any LLM must provide. The key methods are:
Engine 接口(在这里实现)是任何 LLM 都必须提供的通用接口。关键方法有:
- prefill: takes a set of input tokens and generates a KV cache.
- insert: takes a KV cache and inserts it into the batch of KV caches that generate is generating from.
- generate: takes a set of batched KV caches and generates one token per batch entry, appending a single token’s KV cache to the decode state for each token.
- prefill: 接收一组输入 token,生成一份 KV cache。
- insert: 接收一份 KV cache,把它插入 generate 正在据以生成的那批 KV cache 中。
- generate: 接收一组拼批的 KV cache,为每个 batch 条目生成一个 token,并把单个 token 的 KV cache 追加到每个 token 的 decode state 上。
Worked Problems
实战习题
I’m going to invent a new model based on LLaMA-2 13B for this section. Here are the details:
本节我要基于 LLaMA-2 13B 发明一个新模型。细节如下:
| hyperparam | value |
|---|---|
| L (num_layers) | 64 |
| D (d_model) | 4,096 |
| F (ffw_dimension) | 16,384 |
| N (num_heads) | 32 |
| K (num_kv_heads) | 8 |
| H (qkv_dim) | 256 |
| V (num_embeddings) | 32,128 |
| 超参数 | 取值 |
|---|---|
| L (num_layers) | 64 |
| D (d_model) | 4,096 |
| F (ffw_dimension) | 16,384 |
| N (num_heads) | 32 |
| K (num_kv_heads) | 8 |
| H (qkv_dim) | 256 |
| V (num_embeddings) | 32,128 |
Question 1: How many parameters does the above model have? How large are its KV caches per token in int8? You can assume we share the input and output projection matrices.
问题 1: 上面的模型有多少参数?在 int8 下它每个 token 的 KV cache 有多大?可以假设输入和输出投影矩阵是共享的。
Click here for the answer.
点击查看答案。
Parameter count:
参数量:
- MLP parameter count: $L * D * F * 3$
- Attention parameter count: $L * 2 * D * H * (N + K)$
- Vocabulary parameter: $D * V$ (since we share these matrices)
- MLP 参数量:$L * D * F * 3$
- 注意力参数量:$L * 2 * D * H * (N + K)$
- 词表参数:$D * V$(因为我们共享这些矩阵)
Our total parameter count is thus $L * D * (3F + 2H * (N + K)) + D * V$. Plugging in the numbers above, we have 64 * 4096 * (3*16384 + 2 * 256 * (32 + 8)) + 4096 * 32128 = 18.4e9. Thus, this model has about 18.4 billion parameters.
因此总参数量是 $L * D * (3F + 2H * (N + K)) + D * V$。代入上面的数字,得到 64 * 4096 * (3*16384 + 2 * 256 * (32 + 8)) + 4096 * 32128 = 18.4e9。也就是说,这个模型约有 184 亿参数。
The KV caches are $2 * L * K * H$ per token in int8, which is 2 * 64 * 8 * 256 = 262kB per token.
在 int8 下,每个 token 的 KV cache 是 $2 * L * K * H$,即 2 * 64 * 8 * 256 = 262kB 每 token。
Question 2: Say we want to serve this model on a TPUv5e 4x4 slice and can fully shard our KV cache over this topology. What’s the largest batch size we can fit, assuming we use int8 for everything and want to support 128k sequences? What if we dropped the number of KV heads to 1?
问题 2: 假设我们要在 TPUv5e 4x4 slice 上服务这个模型,并能在此拓扑上完全分片 KV cache。假设一切用 int8,且要支持 128k 的序列,我们能装下的最大 batch size 是多少?如果把 KV 头数降到 1 呢?
Click here for the answer.
点击查看答案。
Our KV caches have size $2 \cdot L \cdot K \cdot H$ per token in int8, or 2 * 64 * 8 * 256 = 262kB. For 128k sequences, this means 262e3 * 128e3 = 33.5GB per batch entry. Since each TPU has 16GB of HBM, including our parameters, the largest batch size we can fit is (16 * 16e9 - 18.4e9) / 33.5e9 = 7. If we had $K=1$, we would have 8 times this, aka about 56.
在 int8 下,我们的 KV cache 每 token 大小为 $2 \cdot L \cdot K \cdot H$,即 2 * 64 * 8 * 256 = 262kB。对 128k 序列,这意味着每个 batch 条目 262e3 * 128e3 = 33.5GB。由于每颗 TPU 有 16GB HBM(还要装参数),我们能装下的最大 batch size 是 (16 * 16e9 - 18.4e9) / 33.5e9 = 7。如果 $K=1$,我们会有 8 倍于此,约 56。
Question 3: How long does it take to load all the parameters into the MXU from HBM assuming they’re fully sharded on a TPU v5e 4x4 slice? Assume int8 parameters. This is a good lower bound on the per-step latency.
问题 3: 假设参数在 TPU v5e 4x4 slice 上完全分片,把它们全部从 HBM 加载到 MXU 需要多久?假设参数是 int8。这是每步延迟的一个很好的下界。
Click here for the answer.
点击查看答案。
We have a total of 18.4B parameters, or 18.4e9 bytes in int8. We have 8.2e11 HBM bandwidth per chip, so it will take roughly 18e9 / (8.2e11 * 16) = 1.4ms assuming we can fully use our HBM bandwidth.
我们总共有 18.4B 参数,在 int8 下是 18.4e9 字节。每芯片 HBM 带宽为 8.2e11,所以假设能完全用上 HBM 带宽,大约需要 18e9 / (8.2e11 * 16) = 1.4ms。
Question 4: Let’s say we want to serve this model on a TPUv5e 4x4 slice using int8 FLOPs and parameters/activations. How would we shard it for both prefill and decode? Hint: maybe answer these questions first:
问题 4: 假设我们要在 TPUv5e 4x4 slice 上用 int8 的 FLOPs 和参数 / 激活来服务这个模型。prefill 和 decode 分别该如何分片?提示:也许先回答这几个问题:
- What does ICI look like on a 4x4?
- What’s the roofline bound on tensor parallelism?
- How can we shard the KV caches?
- 4x4 上的 ICI 是什么样?
- 张量并行的 roofline 界限是多少?
- 我们如何分片 KV cache?
For this sharding, what is the rough per-step latency for generation?
对这个分片方案,generation 每步的粗略延迟是多少?
Question 5: Let’s pretend the above model is actually an MoE. An MoE model is effectively a dense model with E copies of the FFW block. Each token passes through k of the FFW blocks and these k are averaged to produce the output. Let’s use E=16 and k=2 with the above settings.
问题 5: 假设上面的模型其实是一个 MoE。MoE 模型实际上就是带 E 份 FFW 块的稠密模型。每个 token 经过其中 k 份 FFW 块,这 k 份的输出取平均作为结果。沿用上面的设置,令 E=16、k=2。
- How many total and activated parameters does it have? Activated means used by any given token.
- What batch size is needed to become FLOPs bound on TPU v5e?
- How large are its KV caches per token?
- How many FLOPs are involved in a forward pass with T tokens?
- 它总共有多少参数、多少激活参数?激活是指任意给定 token 实际会用到的那部分。
- 在 TPU v5e 上需要多大的 batch size 才能变成 FLOPs 受限?
- 它每个 token 的 KV cache 有多大?
- 用 T 个 token 做一次前向传播涉及多少 FLOPs?
Click here for the answer.
点击查看答案。
(1) As an MoE, each MLP block now has $3 * E * D * F$ parameters, an increase of $E$ over the dense variant. Thus it now has $L * D * (3EF + 2H * (N + K)) + D * V$ or 64 * 4096 * (3*16*16384 + 2 * 256 * (32 + 8)) + 4096 * 32128 = 212e9 total parameters, an increase of about 12x. For activated parameters, we have $k$ rather than $E$ activated parameters, for a total of 64 * 4096 * (3*2*16384 + 2 * 256 * (32 + 8)) + 4096 * 32128 = 31.2e9, an increase of less than 2x over the dense variant.
(1) 作为 MoE,每个 MLP 块现在有 $3 * E * D * F$ 个参数,比稠密版本多了 $E$ 倍。于是总参数为 $L * D * (3EF + 2H * (N + K)) + D * V$,即 64 * 4096 * (3*16*16384 + 2 * 256 * (32 + 8)) + 4096 * 32128 = 212e9,增加约 12 倍。至于激活参数,被激活的是 $k$ 而不是 $E$,总共 64 * 4096 * (3*2*16384 + 2 * 256 * (32 + 8)) + 4096 * 32128 = 31.2e9,比稠密版本增加不到 2 倍。
(2) Because we have $E$ times more parameters for only $k$ times more FLOPs, our HBM roofline increases by a factor of $E/k$. That means on a TPU v5e we need about 240 * (16 / 2) = 1920 tokens.
(2) 因为参数多了 $E$ 倍而 FLOPs 只多了 $k$ 倍,我们的 HBM roofline 提高了 $E/k$ 倍。这意味着在 TPU v5e 上大约需要 240 * (16 / 2) = 1920 个 token。
(3) The KV cache size stays the same as the MoE character doesn’t change anything about the attention mechanism.
(3) KV cache 大小不变,因为 MoE 的性质不改变注意力机制的任何东西。
(4) This is still $2 \cdot \text{activated params} \cdot T$. Thus this is $2 * \text{31.2e9} * T$.
(4) 这仍然是 $2 \cdot \text{激活参数量} \cdot T$,即 $2 * \text{31.2e9} * T$。
Question 6: With MoEs, we can do “expert sharding”, where we split our experts across one axis of our mesh. In our standard notation, our first FFW weight has shape [E, D, F] and we shard it as [EZ, DX, FY] where X is only used during training as our FSDP dimension. Let’s say we want to do inference on a TPU v5e:
问题 6: 对 MoE,我们可以做「专家分片」,把专家分到 mesh 的一条轴上。在标准记号下,我们的第一个 FFW 权重形状为 [E, D, F],把它分片成 [EZ, DX, FY],其中 X 只在训练时用作 FSDP 维度。假设我们要在 TPU v5e 上做推理:
- What’s the HBM weight loading time for the above model on a TPU v5e 8x16 slice with Y=8, Z=16? How much free HBM is available per TPU?
- What is the smallest slice we could fit our model on?
- 在 Y=8、Z=16 的 TPU v5e 8x16 slice 上,上面的模型 HBM 加载权重的时间是多少?每颗 TPU 还剩多少空闲 HBM?
- 我们能装下这个模型的最小 slice 是多大?
Question 7 [2D model sharding]: Here we’ll work through the math of what the ESTI paper calls 2D weight-stationary sharding. We describe this briefly in Appendix B, but try doing this problem first to see if you can work out the math. The basic idea of 2D weight stationary sharding is to shard our weights along both the $D$ and $F$ axes so that each chunk is roughly square. This reduces the comms load and allows us to scale slightly farther.
问题 7 [2D 模型分片]: 这里我们来推导 ESTI 论文所称的 2D weight-stationary 分片的数学。我们在附录 B 里简单描述过它,但先试试自己把数学推出来。2D weight stationary 分片的基本思想是把权重同时沿 $D$ 和 $F$ 两条轴分片,让每个分块大致是正方形。这降低了通信负载,让我们能扩展得稍远一些。
Here’s the algorithm for 2D weight stationary:
下面是 2D weight stationary 的算法:
- In[B, DX] = AllGatherYZ(In[B, DXYZ])
- Tmp[B, FYZ] {UX} = In[B, DX] *D Win[DX, FYZ]
- Tmp[B, FYZ] = AllReduceX(Tmp[B, FYZ] {UX})
- Out[B, DX] {UYZ} = Tmp[B, FYZ] *F Wout[FYZ, DX]
- Out[B, DXYZ] = ReduceScatterYZ(Out[B, DX] {UYZ})
Your goal is to work out $T_\text{math}$ and $T_\text{comms}$ for this algorithm and find when it will outperform traditional 3D model sharding?
你的任务是求出这个算法的 $T_\text{math}$ 和 $T_\text{comms}$,并找出它在什么时候会优于传统的 3D 模型分片?
Click here for the answer!
点击查看答案!
Let’s work out $T_\text{math}$ and $T_\text{comms}$. All our FLOPs are fully sharded so as before we have $T_\text{math} = 4BDF / (N \cdot C)$ but our comms are now
我们来推导 $T_\text{math}$ 和 $T_\text{comms}$。我们所有 FLOPs 都完全分片了,所以和之前一样有 $T_\text{math} = 4BDF / (N \cdot C)$,但我们的通信现在是
$$\begin{align*} T_\text{2D comms} = \frac{2BD}{2X \cdot W_\text{ici}} + \frac{4BF}{YZ \cdot W_\text{ici}} + \frac{2BD}{2X \cdot W_\text{ici}} = \frac{2BD}{X \cdot W_\text{ici}} + \frac{4BF}{YZ \cdot W_\text{ici}} \end{align*}$$
where we note that the AllReduce is twice as expensive and we scale our comms by the number of axes over which each operation is performed. Assuming we have freedom to choose our topology and assuming $F=4D$ (as in LLaMA-2), we claim (by some basic calculus) that the optimal values for $X$, $Y$, and $Z$ are $X = \sqrt{N / 8}$, $YZ = \sqrt{8N}$ so the total communication is
注意 AllReduce 的代价是两倍,并且我们按每个操作所跨的轴数来缩放通信量。假设我们可以自由选择拓扑,并假设 $F=4D$(如 LLaMA-2),我们(用一点基础微积分)断言 $X$、$Y$、$Z$ 的最优值是 $X = \sqrt{N / 8}$、$YZ = \sqrt{8N}$,于是总通信为
$$T_\text{2D comms} = \frac{2B}{W_\text{ici}} \left(\frac{D}{X} + \frac{8D}{YZ}\right) = \frac{\sqrt{128} BD}{\sqrt{N} \cdot W_\text{ici}} \approx \frac{11.3 BD}{\sqrt{N} \cdot W_\text{ici}}$$
Firstly, copying from above, normal 1D model parallelism would have $T_\text{model parallel comms} = 4BD / (3 \cdot W_\text{ici})$, so when are the new comms smaller? We have
首先,照抄上面的结果,普通的 1D 模型并行的通信是 $T_\text{model parallel comms} = 4BD / (3 \cdot W_\text{ici})$,那么新的通信什么时候更小?我们有
$$\begin{align*} T_\text{model parallel comms} > T_\text{2D comms} \iff \frac{4BD}{3 \cdot W_\text{ici}} > \frac{\sqrt{128} BD}{\sqrt{N} \cdot W_\text{ici}} \\ \iff N > 128 \cdot \left(\frac{3}{4}\right)^2 = 72 \end{align*}$$
For a general $F$, we claim this condition is
对一般的 $F$,我们断言这个条件是
$$N > 32 \cdot \left(\frac{F}{D}\right) \cdot \left(\frac{3}{4}\right)^2$$
So that tells us if we have more than 72 chips, we’re better off using this new scheme. Now this is a slightly weird result because we’ve historically found ourselves ICI bound at around ~20 way tensor parallelism. But here, even if we’re communication-bound, our total communication continues to decrease with the number of total chips! What this tells us is that we can continue to increase our chips, increase our batch size, do more parameter scaling, and see reduced latency.
这告诉我们,如果芯片数超过 72,用这个新方案更好。这个结果有点奇怪,因为历史上我们发现自己在大约 20 路张量并行时就会撞上 ICI 界限。但在这里,即使我们通信受限,总通信量仍会随着总芯片数继续下降!这说明我们可以继续增加芯片、增大 batch size、做更多参数扩展,同时看到延迟下降。
That’s all for Part 7! For Part 8, with a look at how we might serve LLaMA 3 on TPUs, click here.
第 7 部分到此结束!第 8 部分会看我们如何在 TPU 上服务 LLaMA 3,点这里。
Appendix
附录
Appendix A: How real is the batch size > 240 rule?
附录 A:batch size > 240 这条规则有多真实?
The simple rule we provided above, that our batch size must be greater than 240 tokens to be compute-bound, is roughly true but ignores some ability of the TPU to prefetch the weights while other operations are not using all available HBM, like when doing inter-device communication.
我们上面给出的简单规则——batch size 必须大于 240 个 token 才能计算受限——大致正确,但忽略了 TPU 的某些能力:当其他操作没有用满全部 HBM 带宽时(比如在做设备间通信时),它可以预取权重。
Here’s an empirical plot of layer time (in microseconds) for a small Transformer with dmodel 8192, dff 32768, and only 2 matmuls per layer. This comes from this Colab notebook. You’ll see that step time increases very slowly up until around batch 240, and then increases linearly.
下面是一张经验图,展示一个小 Transformer 的层时间(微秒),其 dmodel 为 8192、dff 为 32768,每层只有 2 次矩阵乘法。它来自这个 Colab notebook。你会看到步时在 batch 大约 240 之前增长非常缓慢,之后开始线性增长。
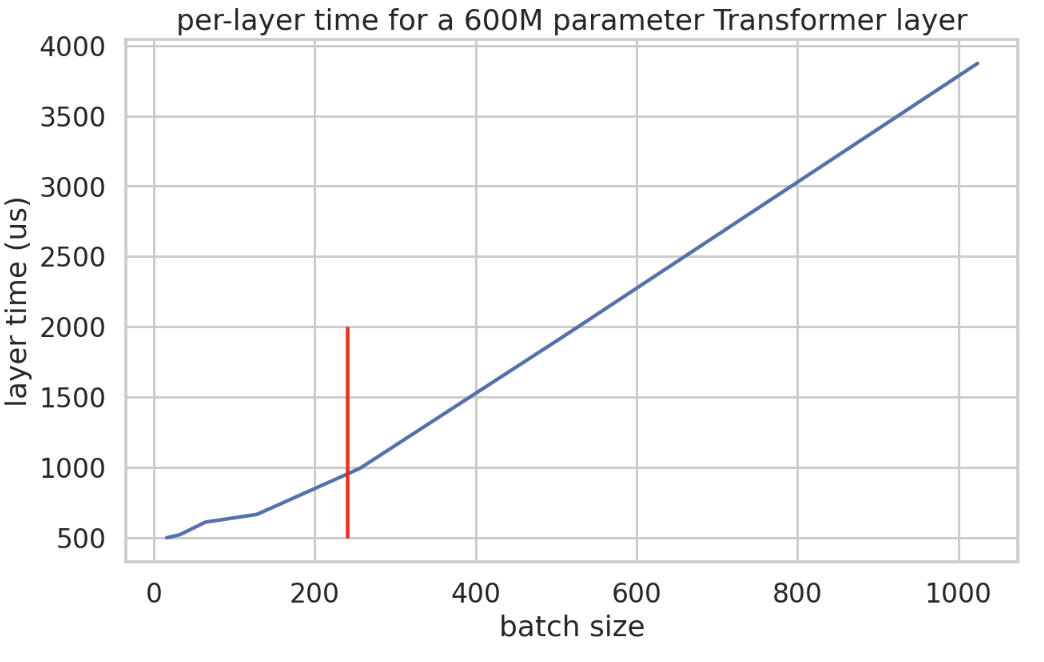
Here’s the actual throughput in tokens / us. This makes the argument fairly clearly. Since our layer is about 600M parameters sharded 4 ways here, we’d expect a latency of roughly 365us at minimum.
下面是实际的吞吐,单位为 tokens / us。这相当清楚地证明了上述论点。由于这里的层约有 600M 参数、分片成 4 份,我们预期延迟至少约为 365us。
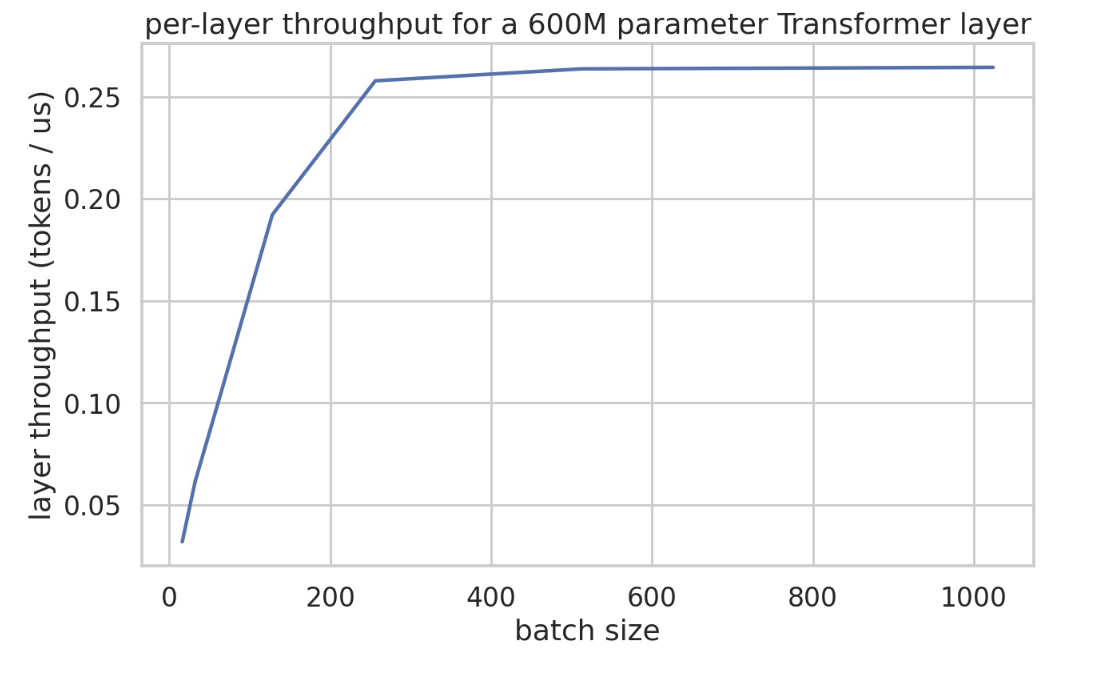
So at least in this model, we do in fact see throughput increase until about BS240 per data parallel shard.
所以至少在这个模型里,我们确实看到吞吐一直增加到每个数据并行分片约 BS240 为止。
Appendix B: 2D Weight Stationary sharding
附录 B:2D Weight Stationary 分片
As the topology grows, if we have access to higher dimensional meshes (like that of TPUs) it is possible to refine this further with “2D Weight Sharding” by introducing a second sharding axis. We call this “2D Weight Stationary”, and was described in more detail in the Efficiently Scaling Transformer Inference paper.
随着拓扑变大,如果我们能使用更高维的 mesh(比如 TPU 的 mesh),就可以通过引入第二条分片轴进一步优化,这称为「2D Weight Sharding」。我们称之为「2D Weight Stationary」,在 Efficiently Scaling Transformer Inference 论文里有更详细的描述。
Because we’re only sharding the hidden $$F$$ dimension in Megatron, it can become significantly smaller than $$E$$ (the $$d_\text{model}$$ dimension) once the number of chips grows large with 1D sharding. This means at larger batch sizes, it can be more economical to perform a portion of the collectives over the hidden dimension after the first layer of the MLP is applied.
因为在 Megatron 里我们只分片隐藏维 $$F$$,当 1D 分片下芯片数变大时,它可能变得比 $$E$$($$d_\text{model}$$ 维度)小得多。这意味着在较大的 batch size 下,在 MLP 第一层做完之后,把一部分集合通信放到隐藏维上做可能更经济。
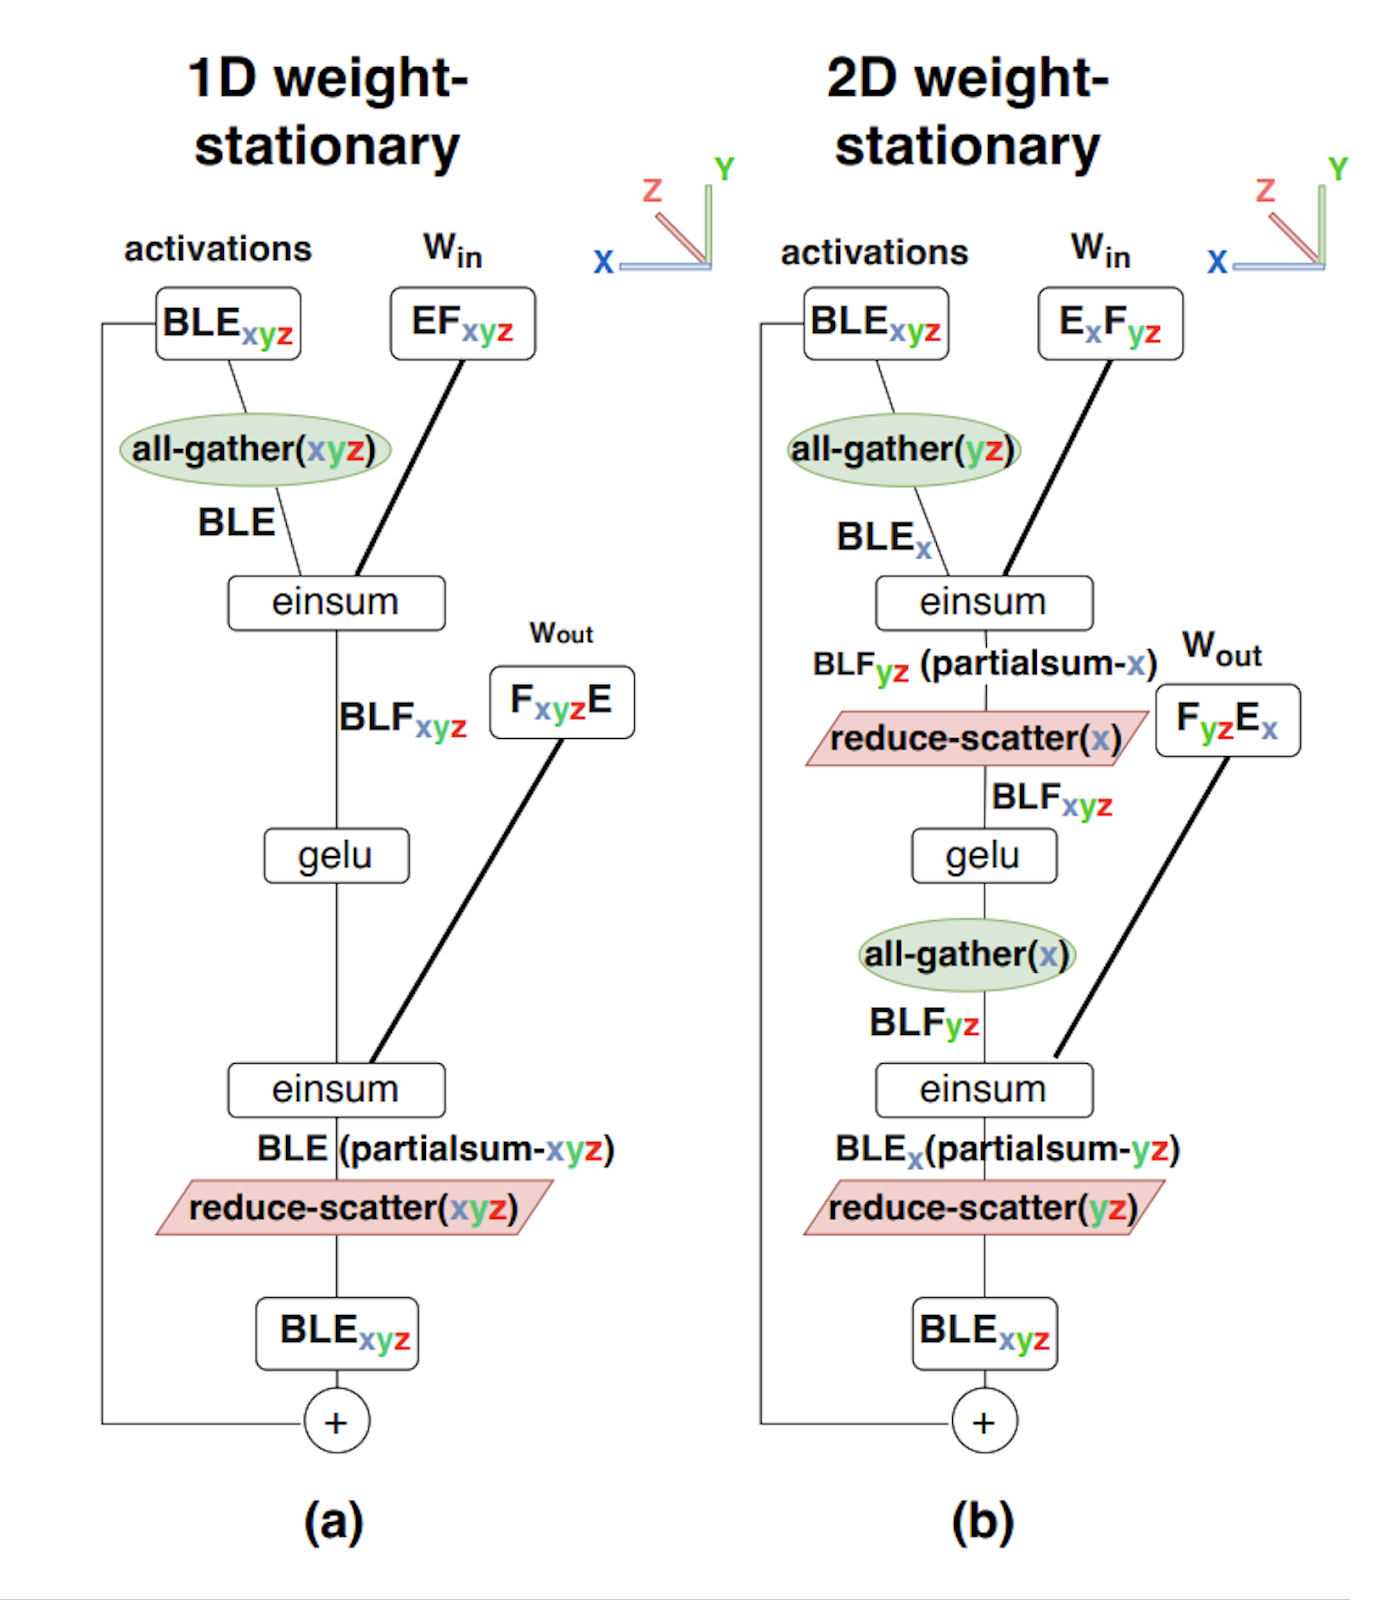
This figure shows:
这张图展示了:
- 1D weight-stationary sharding, a.k.a. Pure Megatron sharding, where activations are fully replicated after AllGather, and weights are fully sharded over the hidden F dimension.
- 2D weight stationary sharding, where weights are sharded over both the hidden F and reduction E dimension, and activations are sharded over the E dimension. We perform an AllGather on the (yz) axis before the first layer, then ReduceScatter on the (x) axis.
- 1D weight-stationary 分片,也叫纯 Megatron 分片:激活在 AllGather 后完全复制,权重沿隐藏维 F 完全分片。
- 2D weight stationary 分片:权重同时沿隐藏维 F 和收缩维 E 分片,激活沿 E 维分片。我们在第一层之前在 (yz) 轴上做 AllGather,然后在 (x) 轴上做 ReduceScatter。
For the attention layer, Megatron style sharding is also relatively simple for smaller numbers of chips. However, Megatron happens over the $$n_\text{heads}$$ dimension, which puts a limit on the amount of sharding that is possible. Modifying the 2D sharding for attention (instead of sharding the hidden dimension, we shard the $$n_\text{heads}$$ dimension), we gain the ability to scale further.
对注意力层来说,在芯片数较少时 Megatron 风格的分片也相对简单。然而 Megatron 是沿 $$n_\text{heads}$$ 维度进行的,这限制了可选的分片数量。把 2D 分片改用到注意力上(不分片隐藏维,而是分片 $$n_\text{heads}$$ 维度),我们就获得了进一步扩展的能力。
Appendix C: Latency bound communications
附录 C:延迟受限的通信
As a recap, in Section 3 we derived the amount of time it takes to perform an AllGather into a tensor of size B on each TPU, over X chips on a 1D ring with links of full-duplex bandwidth of WICI and latency Tmin.
回顾一下,在第 3 节里我们推导了在 1D 环上跨 X 颗芯片做一次 AllGather、每颗 TPU 上得到大小为 B 的张量所需的时间,链路的全双工带宽为 WICI、延迟为 Tmin。
$$T_{total} = \max\left(\frac{T_{min} \cdot |X|}{2}, \frac{B}{W_{ICI}}\right)$$
For large B, the wall clock stays relatively constant because as you add more chips to the system, you simultaneously scale the amount of data movement necessary to perform the operation and the total bandwidth available.
对大的 B,挂钟时间基本保持不变,因为当你向系统加入更多芯片时,完成该操作所需的数据搬运量和可用总带宽会同步增长。
Because of the relatively low amounts of data being moved during latency optimized inference, collectives on activations are often bound by the latency term (especially for small batch sizes). One can visualise the latency quite easily, by counting the number of hops we need to complete before it is completed.
由于面向延迟优化的推理所搬运的数据量相对较少,对激活的集合通信常常受延迟项约束(尤其在小 batch size 下)。我们可以通过数一数操作完成前需要经过多少跳,很容易地把延迟可视化出来。
On TPUs, if the tensor size-dependent part of communication is less than 1 microsecond per hop (a hop is communication between two adjacent devices) we can be bottlenecked by the fixed overhead of actually dispatching the collective. With 4.5e10 unidirectional ICI bandwidth, ICI communication becomes latency bound when: $$(\text{bytes} / n_\text{shards}) / 4.5e10 < 1e-6$$. For 8-way Megatron sharding, this is when buffer_size < 360kB. This actually is not that small during inference: with BS=16 and D=8192 in int8, our activations will use 16*8192=131kB, so we’re already latency bound.
在 TPU 上,如果通信中与张量大小相关的部分每跳小于 1 微秒(一跳是两颗相邻设备之间的通信),我们就可能受限于实际派发集合通信的固定开销。在 4.5e10 的单向 ICI 带宽下,当 $$(\text{字节数} / n_\text{分片数}) / 4.5e10 < 1e-6$$ 时,ICI 通信就变成延迟受限。对 8 路 Megatron 分片,这发生在 buffer_size < 360kB 时。这在推理中其实并不算小: 在 int8 下 BS=16、D=8192 时,我们的激活会用 16*8192=131kB,所以我们已经是延迟受限了。
Takeaway: our comms become latency bound when $$\text{total bytes} < W_{ICI} \times 1e-6$$. For instance, with model parallelism over $$Y$$, we become bound in int8 when $$Y > BD / 45,000$$.
结论: 当 $$\text{总字节数} < W_{ICI} \times 1e-6$$ 时,我们的通信变成延迟受限。例如,在 int8 下对 $$Y$$ 做模型并行时,当 $$Y > BD / 45,000$$ 我们就受限了。
There’s a parallel to be drawn here with the compute roofline — we are incurring the fixed cost of some small operations (latency for comms, memory bandwidth for matmuls).
这里可以画一条与计算 roofline 平行的类比——我们都是在为某些小操作付出固定成本(通信的延迟、矩阵乘法的显存带宽)。
Appendix D: Speculative Sampling
附录 D:投机采样(Speculative Sampling)
When we really care about end to end latency, there is one extra trick we can employ called speculative sampling[spec1][spec2]. As a recap, we usually generate tokens from a large Transformer one by one:
当我们真的在意端到端延迟时,还有一个额外的技巧可用,叫投机采样(speculative sampling)[spec1][spec2]。回顾一下,我们通常从一个大 Transformer 里一个接一个地生成 token:
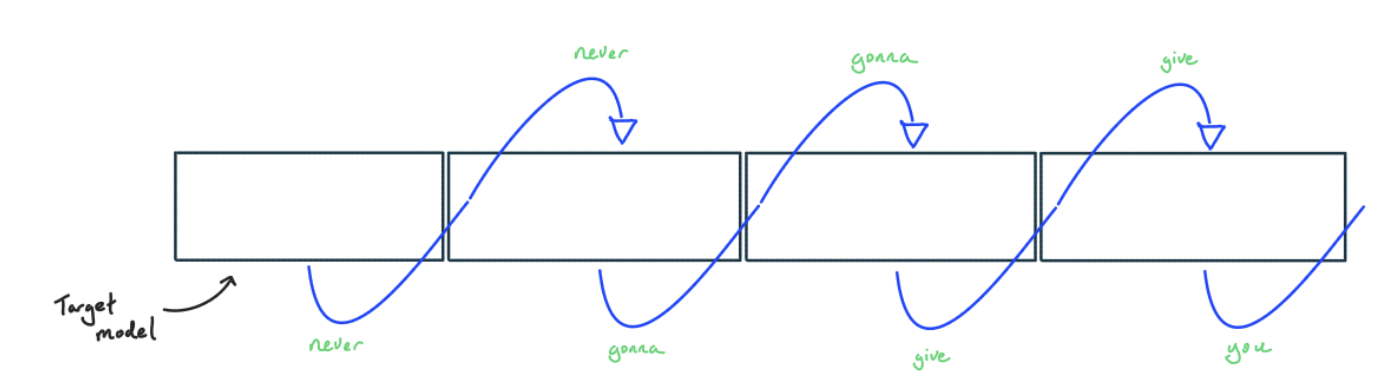
With speculative sampling, we use a smaller, cheaper model to generate tokens and then check the result with the big model. This is easiest to understand with greedy decoding:
用投机采样时,我们用一个更小、更便宜的模型来生成 token,然后用大模型检查结果。用贪心解码最容易理解:
- We sample greedily from some smaller, cheaper model. Ideally we use a model trained to match the larger model, e.g. by distillation, but it could be as simple as simply using n-grams or token matching a small corpus of text.
- After we’ve generated K tokens, we use the big model to compute the next-token logits for all the tokens we’ve generated so far.
- Since we’re decoding greedily, we can just check if the token generated by the smaller model has the highest probability of all possible tokens. If one of the tokens is wrong, we take the longest correct prefix and replace the first wrong token with the correct token, then go back to (1). If all the tokens are correct, we can use the last correct logit to sample an extra token before going back to (1).
- 我们从某个更小、更便宜的模型贪心采样。理想情况下用一个通过蒸馏等方式训练来匹配大模型的模型,但也可以简单到用 n-gram 或在一小段文本语料上做 token 匹配。
- 生成 K 个 token 之后,我们用大模型为目前已生成的所有 token 计算 next-token logits。
- 由于是贪心解码,我们只需检查小模型生成的 token 是否在所有可能 token 中概率最高。如果某个 token 是错的,我们取最长的正确前缀,把第一个错误的 token 换成正确的 token,然后回到 (1)。如果所有 token 都正确,我们可以用最后一个正确的 logit 再额外采样一个 token,然后回到 (1)。
Why is this a latency win? This scheme still requires us to do the FLOPs-equivalent of one forward pass through the big model for every token, but because we can batch a bunch of tokens together, we can do all these FLOPs in one forward pass and take advantage of the fact that we’re not compute-bound to score more tokens for free.
为什么这对延迟是好事? 这个方案仍然要求我们对每个 token 做大模型一次前向传播的等效 FLOPs,但由于我们可以把一堆 token 拼批,我们能在一次前向传播里做完所有这些 FLOPs,并利用我们并非计算受限这一点,免费地给更多 token 打分。
Every accepted token becomes more expensive in terms of FLOPs on average (since some will be rejected, and we have to call a draft model), but we wring more FLOPs out of the hardware, and the small model is cheap, so we win overall. We also share KV cache loads across multiple steps, so speculative decoding can also be a throughput win for long context. Since everything has been checked by the big model, we don’t change the sampling distribution at all (though the exact trajectory will differ for non-greedy).
平均而言,每个被接受的 token 在 FLOPs 上都变得更贵(因为有些会被拒绝,而且我们还得调用一个 draft 模型),但我们从硬件里榨出了更多 FLOPs,而且小模型很便宜,所以总体上是我们赢。我们还在多个步骤之间共享 KV cache 加载,所以投机解码在长上下文下也能带来吞吐收益。 由于一切都经过大模型检查,我们完全没有改变采样分布(不过在非贪心时,具体轨迹会不同)。
Traditionally, speculative decoding relies on the existence of a smaller model with a similar sampling distribution to the target model, e.g. LLaMA-2 2B for LLaMA-2 70B, which often doesn’t exist. Even when this is available, the smaller drafter can still be too expensive if the acceptance rate is low. Instead, it can be helpful to embed a drafter within the main model, for instance by adding a dedicated drafter head to one of the later layers of the base model[eagle][medusa][DeepSeek3]. Because this head shares most of its parameters with the main model, it’s faster to run and matches the sampling distribution more closely.
传统上,投机解码依赖存在一个采样分布与目标模型相似的小模型,例如给 LLaMA-2 70B 配一个 LLaMA-2 2B,但这样的模型往往并不存在。即使存在,如果接受率低,这个小 drafter 也可能太贵。相反,把 drafter 嵌进主模型里会更有帮助,例如在基座模型的某个靠后的层上加一个专用的 drafter head[eagle][medusa][DeepSeek3]。因为这个 head 与主模型共享大部分参数,它跑得更快,也更贴近采样分布。
For normal autoregressive sampling the token/s is the same as the step time. We are still beholden to the theoretical minimum step time according to the Arithmetic Intensity section here (in fact, Speculative Sampling step times are usually quite a bit slower than normal autoregressive sampling, but because we get more than 1 token out per step on average we can get much better tokens/s).
对普通的自回归采样,token/s 等于步时的倒数。我们仍然受本节「算术强度」部分给出的理论最小步时约束(事实上,投机采样的步时通常比普通自回归采样慢不少,但由于平均每步能产出多于 1 个 token,我们可以得到好得多的 tokens/s)。
How does this work for non-greedy decoding? This is a bit more complicated, but essentially boils down to a Metropolis-Hastings inspired algorithm where we have $$P_{\text{draft model}}(\text{chosen token})$$ and $$P_{\text{target model}}(\text{chosen token})$$ derived from the logits, and reject the chosen token probabilistically if the ratio of these probabilities is smaller than some threshold.
这在非贪心解码下如何工作? 这稍微复杂一些,但本质上归结为一个受 Metropolis-Hastings 启发的算法:我们从 logits 得到 $$P_{\text{draft model}}(\text{被选中的 token})$$ 和 $$P_{\text{target model}}(\text{被选中的 token})$$,如果这两个概率之比小于某个阈值,就以一定概率拒绝被选中的 token。
Takeaway: Speculative sampling is yet another powerful lever for trading throughput for better per token latency. However, in the scenario where batch size is limited (e.g. small hardware footprint or large KV caches), it becomes a win-win.
结论: 投机采样是又一个强大的杠杆,用吞吐换取更好的每 token 延迟。然而在 batch size 受限的场景下(例如硬件占用小、或 KV cache 很大),它变成一个双赢选择。
讨论
用 GitHub 账号留言;评论保存在公开仓库chengshu-blog-discussions的 Discussions 里。也可通过 RSS 订阅后续文章。